The shift is from information to delegated action.
An agent adds a new route through the internet: describe what you want, then let a system choose tools and take some of the steps. That could widen access while giving new intermediaries influence over what people see, whom they buy from and which work gets paid for.
From answering to acting
An assistant can explain a market. An agent preparing a weekly market brief may search, compare, calculate and revise across tools. The change is delegated action between your instruction and the final response.
A useful personal agent also needs relevant memory, service access, a budget, checks and permission boundaries. Memory must allow correction and deletion: a preference stored six months ago may no longer be yours.
Act, check and return control
- 1. Set the goalName the result, owner, budget and permitted actions.
- 2. Use relevant contextRead approved documents and correct outdated memory.
- 3. Act and checkUse tools; verify the result against the goal.
- 4. Return controlShow the result and log; ask before client delivery.
Stop when checks fail
Illustrative brief-preparation cycle, not an Atlas test. Connected systems must enforce permissions.
A global transition, with uneven access
There is no single percentage for “how much the world uses AI.” Surveys and telemetry measure different populations. One consistent methodology can show variation without removing its coverage gaps.
Language, connectivity, mobile access, available services and payment systems shape which tasks are practical. High model capability in one market does not establish broad access elsewhere. General AI use also does not measure autonomous-agent adoption.
EU and US: adoption is only the first step
A common survey makes the EU–US comparison more useful. The European Investment Bank’s 2025 results show similar generative AI adoption, but a larger difference in breadth. The panels have different denominators: adopting AI and using it across processes are separate questions.
Count useful outcomes, not just agents
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools.
Judge a workflow by acceptable results and total cost, including review, corrections, failed runs and integration—not the number of drafts it generates.
Microsoft reports 15× as many active agents in one year
15×as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft.
Agent activity is not a count of people, successful outcomes or global productivity.
Definition & scope
At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
The internet becomes a place agents can act
An answer without a visit to its source changes discovery. Pew’s study of US Google browsing found fewer traditional-result clicks on visits with an AI summary.
Services may increasingly respond to agent requests. Cloudflare’s open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make them discoverable and callable; a specification does not establish adoption or dependable transactions.
Publishers still need credit and payment for original work. Brands need their offers understood accurately. The question is whose interests guide selection: user preferences, advertising, commissions and platform priorities can conflict.
Providers describe competing directions: persistent personal assistance at OpenAI and Google; work and usage patterns at Microsoft and Anthropic; Chinese model and tooling ecosystems around DeepSeek and Qwen; another work-and-coding route at Mistral. These are attributed strategies, not an independent ranking. Access, licenses and capabilities vary.
Three questions shape the debate
These are attributed perspectives, not a direct debate or a representative survey. They differ on what counts as capability, control and progress. Names link to the original sources.
Can agents plan?
Mollick sees more scope in current systems; LeCun emphasizes world models for planning; Li distinguishes convincing renderings from accurate simulations.
Ethan Mollick
Wharton professor and author
Models may coordinate more work than he expected. Long organizational tasks remain uncertain: experiment, without assuming people are dispensable.
Yann LeCun
NYU · AMI Labs executive chairman; ex-Meta
Planning needs world models and abstraction that represent consequences.
Fei-Fei Li
Stanford HAI · World Labs cofounder and CEO
Convincing rendering does not guarantee accurate simulation.
Who carries responsibility?
Bengio asks what evidence makes autonomy acceptable; Schneier asks which people remain answerable. These concerns overlap.
Yoshua Bengio
LawZero · leads its safety approach
Greater autonomy needs independent safety evidence, accountability and international coordination.
Bruce Schneier
Inrupt · user-controlled data interests
Hold those configuring and deploying agents responsible; “going rogue” should not obscure human decisions.
Who benefits?
Efficiency is not a shared definition of progress. Expertise, verified benefits, useful tools, customer control and local access are different tests.
Daron Acemoglu, David Autor & Simon Johnson
MIT · foundation funding; Autor discloses Google fellowship support
Choose systems that expand expertise and create tasks. Replacing work is a different design and institutional choice.
Abeba Birhane
Trinity College Dublin · AI Accountability Lab; critical policy perspective
Adoption alone is not progress. Demand evidence of benefits and attend to communities’ needs.
Simon Willison
Applied-AI practitioner · sponsors and past vendor compensation disclosed
Practical value comes from tools and feedback that let a system check its work.
Nithin Kamath
Zerodha cofounder · India; brokerage operator with API access
Customers may build their own interfaces while brokers supply the underlying services. He sees an opening for Zerodha, but remains pessimistic about AI’s wider impact.
Nandan Nilekani
Infosys cofounder · India; funds AI4Bharat
Start with useful applications and access in local languages. Match model size to the task, and build public infrastructure that helps people use it.
Three possible paths: 2029, 2031 and 2036
These Atlas scenarios start in October 2026. Different regions and sectors could experience different combinations. They carry no probabilities or assumed AGI date. Watch completed tasks, intervention rates, total cost, provider switching and control of the customer relationship.
User-controlled delegation
- 2029
- Useful tasks work across services.
- 2031
- Recurring work uses portable context.
- 2036
- Personal agents become a common front door to services.
Watch for: Dependable results, usable permissions and easy switching support this path; lock-in and heavy rework weaken it.
Platform gatekeeping
- 2029
- Integrated ecosystems offer the easiest experience.
- 2031
- More discovery and transactions pass through their agents.
- 2036
- A few intermediaries strongly influence customer access and creator income.
Watch for: Concentrated distribution supports this path; easy switching and durable direct relationships weaken it.
Uneven automation
- 2029
- Bounded tasks improve; long chains still need intervention.
- 2031
- Controlled environments progress faster than open-web work.
- 2036
- Agents coexist with apps and human services.
Watch for: Repeated, economical success on long tasks across organizations and languages would weaken this path.
What supports the answer?
Reported finding: Global adoption needs a defined denominator
Reported findingThe Q2 2026 Microsoft report estimates generative AI use among people aged 15–64 at about 19% worldwide, rounded to the nearest percentage point. Selected economy values use the same report vintage.
Scope and conditions: Modeled telemetry with adjustments and residual coverage bias; no claim of precise national ranking or agent adoption.
Vendor claim · origin, not a quality ratingSource passage · 2026Estimates for ages 15–64, based on adjusted Microsoft telemetry. Not agent adoption, a census or a capability ranking. All chart values use this report vintage.
PDF pages 2, 5 and 13–16: definitions, global periods and economy tables About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2025Adjustments cover telemetry consent, devices, internet access and population. Desktop and Microsoft-user bias remains; estimates can be revised.
Sections 2 and 4: construction and limitations About the source and its versionReported finding: Similar adoption can hide different breadth of use
Reported findingEIBIS reports generative AI adoption of 37% in EU firms and 36% in US firms. Among AI-using firms, 55% and 81% respectively use it in at least two processes.
Scope and conditions: 2025 survey; value-added weights. Different denominators in the two comparisons; no significance claim for the one-point adoption gap.
Independent evidence · origin, not a quality ratingSource passage · 2025April–July 2025 interviews. Four main sectors, firms from five employees; results weighted by value added. The original says at least two processes, despite different wording in the press release.
PDF pages 6, 33–34 and 49–50: weighting, AI results and sample About the source and its versionReported finding: More active agents does not establish better outcomes
Reported findingMicrosoft reports 15 times as many active agents in the measured Microsoft 365 ecosystem between March 2025 and March 2026.
Scope and conditions: Active means at least one day of user-initiated usage or one autonomous run in a rolling 28-day period. The reported ratio does not count successful tasks or global users.
Vendor claim · origin, not a quality ratingSource passage · 2026The chart uses only agent telemetry, March 2025 to March 2026. Active means user-initiated activity on at least one day or at least one autonomous run in 28 days. No absolute counts or global agent market share.
Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodology About the source and its versionReported finding: AI summaries and fewer outbound clicks were associated
Reported findingPew observed traditional-result clicks on 8% of Google search visits with an AI summary and 15% without one.
Scope and conditions: US browsing study, March 2025; search results reconstructed in April. Observational association, not a causal global traffic estimate.
Independent evidence · origin, not a quality ratingSource passage · 2025900 US adults; browsing in March 2025, results reconstructed in April. Query differences may confound the comparison. Not a causal estimate or a current global traffic measure.
Traditional-result clicks and methodology About the source and its versionReported finding: AI's productivity effect depends on the work and measurement
Reported findingA published customer-support study found an average 15% increase in resolved issues per hour. METR's later developer update highlights difficulty estimating current effects.
Scope and conditions: Different settings and designs, not opposing universal verdicts. The support study concerns human workers, not autonomous agents.
Independent evidence · origin, not a quality ratingSource passage · 2025Published QJE version: 5,172 support workers, average 15% increase in issues resolved per hour. One firm's rollout; human support agents, not autonomous software agents. Results vary by experience.
Abstract and productivity results in the published version About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Later experiments face selection and measurement problems. Neither the earlier slowdown estimate nor newer raw estimates establish a general current effect for developers.
Discussion of selection, time measurement and interpretation About the source and its versionArchitecture described: An agent combines a model with tools and feedback
Architecture describedAn agent can attempt steps, observe tool results and revise its approach. A system still needs a goal, access boundaries and checks on its output.
Scope and conditions: The diagram is a conceptual synthesis, not an Atlas product test or a universal implementation.
Independent evidence · origin, not a quality ratingSource passage · 2026Current guide version consulted; exact chapter publication day not established. His disclosures include sponsors, early product access, applied-AI work and previous OpenAI compensation: https://simonwillison.net/about/
Definition of agents, tool loops and verification About the source and its versionArchitecture described: Several competing product paths are emerging
Architecture describedAnnouncements and documentation span persistent personal assistance, enterprise workflows, coding agents and efficiency-focused models.
Scope and conditions: Provider descriptions identify directions; they do not establish a winner, complete availability or comparative reliability.
Vendor claim · origin, not a quality ratingSource passage · 2026A provider description of persistent agents, connected apps and computer environments. Rollout and regional access vary; Atlas has not tested the product for this article.
Product description and rollout qualifications About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Gemini Spark and proactive assistance are described by the provider. Announcement, beta and roadmap are not equivalent to universal availability.
Personal assistance and connected-tool plans About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Own-platform evidence. Product context and methodology matter; it is not a global market share or a directly continuous historical series.
Agentic task patterns and changes to collection methodology About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Efficiency and agent capabilities are provider claims. No independent benchmark replication or blanket license claim is made here.
Efficiency and agent-task emphasis About the source and its versionVendor claim · origin, not a quality ratingSource passage · 20262026 denotes the documentation version consulted, not the repository's first release. Framework licensing does not establish the license of every model used with it.
README: tools, planning, integrations and framework license About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Work and coding workflows are described by the provider, not tested by Atlas in this article.
Context, permissions and reusable work instructions About the source and its versionAuthor hypothesis · not established: Mollick, LeCun and Li emphasize different capability questions
Author hypothesis · not establishedMollick has revised his view of agent organization; LeCun argues for world models and planning; Li distinguishes convincing renderings from accurate simulations.
Scope and conditions: Attributed assessments, not consensus or a head-to-head experiment. Their roles and interests are disclosed in the source records.
Independent evidence · origin, not a quality ratingSource passage · 2026Wharton professor and author. This is his revised assessment of agent organization, not a representative productivity study. Events mentioned in the essay are not independently verified here.
Revised view of agent organization and closing reservations About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Winter/Spring 2026. LeCun is an NYU professor and AMI Labs executive chairman, formerly at Meta; Manyika has Google ties. Institutional publication does not remove those interests.
Discussion of world models, abstraction and planning; participant biographies About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Li is also World Labs cofounder and CEO. Only her remarks are attributed to her; other participants' statements remain separate.
Li's distinction between convincing renderings and accurate simulations About the source and its versionAuthor hypothesis · not established: Safety and responsibility need separate questions
Author hypothesis · not establishedBengio calls for independent safety evidence and oversight; Schneier emphasizes responsibility for how agents are configured and deployed.
Scope and conditions: Different emphases, not a staged direct debate. No catastrophe probability or incident attribution is established by this article.
Independent evidence · origin, not a quality ratingSource passage · 2026Bengio leads LawZero, which pursues its own safety approach. Safety proposals and risk judgments are not measured probabilities or an AGI arrival date.
Independent safety evidence, accountability and international cooperation About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Schneier works with Inrupt, which has an interest in user-controlled data. The article, not its comments, supports the attributed perspective. Specific incidents are not independently investigated here.
Responsibility, configuration and descriptions of unwanted agent behavior About the source and its versionAuthor hypothesis · not established: Who benefits is partly a design and institutional choice
Author hypothesis · not establishedAcemoglu, Autor and Johnson prioritize expertise and new tasks; Birhane asks for evidenced benefits. Willison explains the working feedback loop. Kamath sees customer-built interfaces changing brokerage distribution, while Nilekani emphasizes local-language access and useful applications.
Scope and conditions: Conceptual and normative positions, not measured universal effects. Institutional and financial interests are included in source records.
Independent evidence · origin, not a quality ratingSource passage · 2026A framework for choices about tasks and human expertise, not a guarantee of wage gains. Funding disclosures include foundations and Autor's Google Technology and Society Visiting Fellows support.
Abstract, technology categories, expertise and new tasks; acknowledgments About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Birhane leads Trinity College Dublin's AI Accountability Lab. The published interview was read; the full video was not reviewed. Her policy judgments are distinct from measured effects.
Demanding evidence of benefits; community needs and unequal consequences About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Current guide version consulted; exact chapter publication day not established. His disclosures include sponsors, early product access, applied-AI work and previous OpenAI compensation: https://simonwillison.net/about/
Definition of agents, tool loops and verification About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Company-published interview, edited for clarity. Kamath has a commercial interest in Zerodha and its API-enabled brokerage. His forecast about customer interfaces is an operating perspective, not verified adoption or investment advice.
Episode transcript: AI question, custom interfaces and API access; wider impact About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2025Original interview, edited for clarity and brevity. Nilekani is an Infosys cofounder and supports AI4Bharat. His preference for local-language access and task-specific models is an attributed position, not a benchmark result or a voice for all of India.
Questions about useful applications, local languages, model size and AI4Bharat About the source and its versionAuthor hypothesis · not established: The three paths are conditional Atlas scenarios
Author hypothesis · not establishedUser-controlled delegation, platform gatekeeping and uneven automation describe possible combinations of capability, access and control at three, five and ten years.
Scope and conditions: No probabilities, adoption forecasts or AGI deadlines are estimated. The sources motivate assumptions, not the dates or eventual outcomes.
Vendor claim · origin, not a quality ratingSource passage · 2026A provider's proposed direction and commercial interest, not proof that websites or traditional search disappear.
Discovery, callable services and transactions About the source and its versionVendor claim · origin, not a quality ratingSource passage · 2026Specification version date. Described interoperability is not evidence of widespread adoption or independently tested transaction reliability.
Profiles, capabilities and version negotiation About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Current guide version consulted; exact chapter publication day not established. His disclosures include sponsors, early product access, applied-AI work and previous OpenAI compensation: https://simonwillison.net/about/
Definition of agents, tool loops and verification About the source and its versionIndependent evidence · origin, not a quality ratingSource passage · 2026Bengio leads LawZero, which pursues its own safety approach. Safety proposals and risk judgments are not measured probabilities or an AGI arrival date.
Independent safety evidence, accountability and international cooperation About the source and its version
Where this explanation stops.
- There is no verified global population measure of autonomous-agent adoption in this article. General AI use, firm adoption and one vendor's agent activity are separate measures.
- Product announcements and individual views are attributed to their authors. They do not establish comparative model superiority, universal availability or a research consensus.
- Atlas has not tested cross-provider delegation or commerce for this explanation. The scenarios explore choices without assigning probabilities.
What to take with you
The central shift is who chooses the next step: a person visiting services, or an agent selecting and using them. Capability alone will not decide the outcome; access, incentives and the ability to stop or switch matter too.
Follow the answer back to its sources.
Browse 25 source records
Global AI Diffusion: Q2 2026
Microsoft AI Economy Institute
Microsoft AI Economy Institute · Version consulted on 23 October 2026
Estimates for ages 15–64, based on adjusted Microsoft telemetry. Not agent adoption, a census or a capability ranking. All chart values use this report vintage.
Source passages, license and conditions ↗
Measuring AI Diffusion
A. Misra and colleagues, Microsoft
Microsoft Research · Version consulted on 23 October 2026
Adjustments cover telemetry consent, devices, internet access and population. Desktop and Microsoft-user bias remains; estimates can be revised.
Source passages, license and conditions ↗
EIB Investment Survey 2025: EU overview
European Investment Bank Economics Department
European Investment Bank Economics Department · Version consulted on 23 October 2026
April–July 2025 interviews. Four main sectors, firms from five employees; results weighted by value added. The original says at least two processes, despite different wording in the press release.
Source passages, license and conditions ↗
Agents, human agency, and the opportunity for every organization
Microsoft
Microsoft · Version consulted on 23 October 2026
The chart uses only agent telemetry, March 2025 to March 2026. Active means user-initiated activity on at least one day or at least one autonomous run in 28 days. No absolute counts or global agent market share.
Source passages, license and conditions ↗
Google users are less likely to click on links when an AI summary appears in the results
Pew Research Center
Pew Research Center · Version consulted on 23 October 2026
900 US adults; browsing in March 2025, results reconstructed in April. Query differences may confound the comparison. Not a causal estimate or a current global traffic measure.
Source passages, license and conditions ↗
Generative AI at Work
Erik Brynjolfsson, Danielle Li and Lindsey R. Raymond
The Quarterly Journal of Economics · Version consulted on 23 October 2026
Published QJE version: 5,172 support workers, average 15% increase in issues resolved per hour. One firm's rollout; human support agents, not autonomous software agents. Results vary by experience.
Source passages, license and conditions ↗
We are Changing our Developer Productivity Experiment Design
METR
METR · Version consulted on 23 October 2026
Later experiments face selection and measurement problems. Neither the earlier slowdown estimate nor newer raw estimates establish a general current effect for developers.
Source passages, license and conditions ↗
What is agentic engineering?
Simon Willison
Simon Willison’s Weblog · Version consulted on 23 October 2026
Current guide version consulted; exact chapter publication day not established. His disclosures include sponsors, early product access, applied-AI work and previous OpenAI compensation: https://simonwillison.net/about/
Source passages, license and conditions ↗
The Dot and the Swarm
Ethan Mollick
One Useful Thing · Version consulted on 23 October 2026
Wharton professor and author. This is his revised assessment of agent organization, not a representative productivity study. Events mentioned in the essay are not independently verified here.
Source passages, license and conditions ↗
Learning Abstractions: A Conversation with Yann LeCun
Yann LeCun and James Manyika
Dædalus / American Academy of Arts and Sciences · Version consulted on 23 October 2026
Winter/Spring 2026. LeCun is an NYU professor and AMI Labs executive chairman, formerly at Meta; Manyika has Google ties. Institutional publication does not remove those interests.
Source passages, license and conditions ↗
Professor Yoshua Bengio’s speech to the UN Security Council
Yoshua Bengio
Yoshua Bengio’s website · UN Security Council speech · Version consulted on 23 October 2026
Bengio leads LawZero, which pursues its own safety approach. Safety proposals and risk judgments are not measured probabilities or an AGI arrival date.
Source passages, license and conditions ↗
AI for Good
Abeba Birhane, interviewed by Alix Dunn; AI Now Institute
AI Now Institute · Version consulted on 23 October 2026
Birhane leads Trinity College Dublin's AI Accountability Lab. The published interview was read; the full video was not reviewed. Her policy judgments are distinct from measured effects.
Source passages, license and conditions ↗
Building Pro-Worker Artificial Intelligence
Daron Acemoglu, David Autor and Simon Johnson
The Hamilton Project / Brookings · Version consulted on 23 October 2026
A framework for choices about tasks and human expertise, not a guarantee of wage gains. Funding disclosures include foundations and Autor's Google Technology and Society Visiting Fellows support.
Source passages, license and conditions ↗
Why Governing World Models Is AI’s Next Big Policy Challenge
Stanford HAI; Fei-Fei Li, Amy Zegart and Russell Wald
Stanford HAI · Version consulted on 23 October 2026
Li is also World Labs cofounder and CEO. Only her remarks are attributed to her; other participants' statements remain separate.
Source passages, license and conditions ↗
I Want Better Reporting on AI Genie Behavior
Bruce Schneier
Schneier on Security · Version consulted on 23 October 2026
Schneier works with Inrupt, which has an interest in user-controlled data. The article, not its comments, supports the attributed perspective. Specific incidents are not independently investigated here.
Source passages, license and conditions ↗
Introducing dots
OpenAI
OpenAI · Version consulted on 23 October 2026
A provider description of persistent agents, connected apps and computer environments. Rollout and regional access vary; Atlas has not tested the product for this article.
Source passages, license and conditions ↗
The next evolution of the Gemini app
Google · Version consulted on 23 October 2026
Gemini Spark and proactive assistance are described by the provider. Announcement, beta and roadmap are not equivalent to universal availability.
Source passages, license and conditions ↗
Anthropic Economic Index: Cadences
Anthropic
Anthropic · Version consulted on 23 October 2026
Own-platform evidence. Product context and methodology matter; it is not a global market share or a directly continuous historical series.
Source passages, license and conditions ↗
DeepSeek V4.1 Flash
DeepSeek
DeepSeek · Version consulted on 23 October 2026
Efficiency and agent capabilities are provider claims. No independent benchmark replication or blanket license claim is made here.
Source passages, license and conditions ↗
Qwen-Agent
Qwen team, Alibaba
GitHub · QwenLM/Qwen-Agent · Version consulted on 23 October 2026
2026 denotes the documentation version consulted, not the repository's first release. Framework licensing does not establish the license of every model used with it.
Source passages, license and conditions ↗
Vibe Agent
Mistral AI
Mistral AI · Version consulted on 23 October 2026
Work and coding workflows are described by the provider, not tested by Atlas in this article.
Source passages, license and conditions ↗
Building an open Agentic Internet
Cloudflare
Cloudflare · Version consulted on 23 October 2026
A provider's proposed direction and commercial interest, not proof that websites or traditional search disappear.
Source passages, license and conditions ↗
Universal Commerce Protocol: specification overview
Universal Commerce Protocol contributors
Universal Commerce Protocol documentation · Version consulted on 23 October 2026
Specification version date. Described interoperability is not evidence of widespread adoption or independently tested transaction reliability.
Source passages, license and conditions ↗
Welcome to The Back Office
Nithin Kamath, interviewed by Bhuvan and Rohit
Z-Connect by Zerodha · Interview consulted on 23 October 2026
Company-published interview, edited for clarity. Kamath has a commercial interest in Zerodha and its API-enabled brokerage. His forecast about customer interfaces is an operating perspective, not verified adoption or investment advice.
Source passages, license and conditions ↗
Why the world should stop obsessing over LLMs
Nandan Nilekani, interviewed by Mehboob Jeelani and Itika Sharma Punit
Rest of World · Interview consulted on 23 October 2026
Original interview, edited for clarity and brevity. Nilekani is an Infosys cofounder and supports AI4Bharat. His preference for local-language access and task-specific models is an attributed position, not a benchmark result or a voice for all of India.
Source passages, license and conditions ↗
How this version was checked
AI-reviewed by a separate editorial agent · 23 October 2026. The approval applies to revision 4, its text, visuals and source references.
Chosen to connect measurable adoption with the less settled questions of delegation, control and business response. Regional evidence is kept regional; vendor descriptions are distinguished from independent findings and editorial scenarios.
AI-reviewed by a separate editorial agent · Ask the editor
What changed, and why.
This history comes from saved content versions. A new revision can be an editorial change; it does not by itself mean that the underlying facts changed.
Editorial change · revision 4
Grouped perspectives by question, added two Indian voices, clarified chart takeaways and illustrated the delegation cycle. Business guidance moves to a companion Playbook.
Compare revision 3 with 4
Section order
From answering to acting → A global transition, with uneven access → EU and US: adoption is only the first step → Count useful outcomes, not just agents → The internet becomes a place agents can act → What prominent voices disagree about → Three possible paths: 2029, 2031 and 2036 → What brands and companies should do
From answering to acting → A global transition, with uneven access → EU and US: adoption is only the first step → Count useful outcomes, not just agents → The internet becomes a place agents can act → Three questions shape the debate → Three possible paths: 2029, 2031 and 2036
Section: From answering to acting
Ask an assistant to explain a market and it returns information. Ask an agent to prepare a weekly market brief and it may search, read, compare, calculate and revise a draft across several tools. The important change is delegated action: the system can do work between your instructions and its final response. A useful personal agent would need more than a capable model. It would need relevant memory, access to the right services, a budget, a way to check results and a clear account of what it may do without asking. Memory would need correction and deletion as well as recall. A preference stored six months ago is not automatically your preference today.
An assistant can explain a market. An agent preparing a weekly market brief may search, compare, calculate and revise across tools. The change is delegated action between your instruction and the final response. A useful personal agent also needs relevant memory, service access, a budget, checks and permission boundaries. Memory must allow correction and deletion: a preference stored six months ago may no longer be yours.
Inline visual: From answering to acting
A personal agent needs a controlled working loop Set the goal: Name the result, owner, budget and permitted actions. Use relevant context: Read approved documents and correct outdated memory. Act and check: Use tools, inspect the result and stop when checks fail. Return control: Show the result and action log; ask before sending it to a client. Illustrative meeting-brief workflow; not an Atlas test. Permissions must be enforced by the connected systems.
Act, check and return control Set the goal: Name the result, owner, budget and permitted actions. Use relevant context: Read approved documents and correct outdated memory. Act and check: Use tools; verify the result against the goal. Return control: Show the result and log; ask before client delivery. Cycle returns to the first step; exit: Stop when checks fail Illustrative brief-preparation cycle, not an Atlas test. Connected systems must enforce permissions.
Section: A global transition, with uneven access
There is no single trustworthy percentage for “how much the world uses AI.” Surveys ask different questions; telemetry sees different users; companies and individuals are different populations. One consistent methodology can reveal variation without resolving all those differences. An agent future built around an English-speaking office worker is only one future. Language, mobile access, service availability, connectivity and local payment systems can change which tasks are practical. High model capability in one market does not establish broad access in another. Nor does a country's adoption share tell us how many people use agents autonomously.
There is no single percentage for “how much the world uses AI.” Surveys and telemetry measure different populations. One consistent methodology can show variation without removing its coverage gaps. Language, connectivity, mobile access, available services and payment systems shape which tasks are practical. High model capability in one market does not establish broad access elsewhere. General AI use also does not measure autonomous-agent adoption.
Inline visual: A global transition, with uneven access
Estimated generative AI use · selected economies · Q2 2026 Microsoft AI Economy Institute Selected economies · People aged 15–64 · share estimated to use generative AI United Arab Emirates: 73% France: 50% United States: 33% Germany: 32% South Africa: 24% Brazil: 20% India: 19% China: 18% World estimate: 19% Reported world estimates · same report vintage H2 2025: 16% Q1 2026: 18% Q2 2026: 19% Modeled from Microsoft telemetry, not a census. China coverage omits several widely used domestic tools; including them would be expected to raise its estimate. Percentages are rounded to whole points for display; bar lengths use the published values. Adjustments do not remove all desktop and Microsoft coverage bias. Selected economies illustrate variation, not whole continents or an EU average. The world figure is the report’s estimate, not a mean of the displayed countries. H2 2025 is a half-year label; Q1 and Q2 2026 are quarters. These are reported period estimates, not equally spaced observations or forecasts.
Use spans 18–73% in these economies; the world estimate is 19% Microsoft AI Economy Institute Selected economies · Estimated generative AI use · ages 15–64 · Q2 2026 United Arab Emirates: 73% (emphasized) France: 50% United States: 33% Germany: 32% South Africa: 24% Brazil: 20% India: 19% China: 18% (emphasized) World: 19% World estimate rose from 16% to 19% · reported periods H2 2025: 16% Q1 2026: 18% Q2 2026: 19% Modeled from Microsoft telemetry, not a census. China coverage omits several widely used domestic tools; including them would be expected to raise its estimate. Percentages are rounded to whole points for display; bar lengths use the published values. Adjustments do not remove all desktop and Microsoft coverage bias. Selected economies illustrate variation, not whole continents or an EU average. The world figure is the report’s estimate, not a mean of the displayed countries. H2 2025 is a half-year label; Q1 and Q2 2026 are quarters. These are reported period estimates, not equally spaced observations or forecasts.
Section: EU and US: adoption is only the first step
A common survey is more informative than comparing unrelated national statistics. The European Investment Bank's 2025 results put reported generative AI adoption at similar levels in the EU and US, while revealing a larger difference in how broadly AI is used. The panels have different denominators. They suggest why “we have adopted AI” is an incomplete management metric: it says little about what work has changed or whether the result improved.
A common survey makes the EU–US comparison more useful. The European Investment Bank’s 2025 results show similar generative AI adoption, but a larger difference in breadth. The panels have different denominators: adopting AI and using it across processes are separate questions.
Section: Count useful outcomes, not just agents
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools. The practical question is whether a workflow produces more acceptable work at a sustainable total cost. Include review, corrections, failed runs and integration work. A system that generates ten drafts but requires extensive repair has not necessarily outperformed one careful human draft.
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools. Judge a workflow by acceptable results and total cost, including review, corrections, failed runs and integration—not the number of drafts it generates.
Inline visual: Count useful outcomes, not just agents
Activity inside one provider’s ecosystem Microsoft 15× as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft. Agent activity is not a count of people, successful outcomes or global productivity. At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
Microsoft reports 15× as many active agents in one year Microsoft 15× as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft. Agent activity is not a count of people, successful outcomes or global productivity. At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
Section: The internet becomes a place agents can act
If an agent answers a question without sending the person to the source, the economics of discovery change. Pew's study of US Google browsing found fewer traditional-result clicks on visits with an AI summary. Sites can still supply the information, services and relationships behind an agent's answer. What may change is the route to them: from a person choosing links to a system selecting sources and requesting actions. Cloudflare's open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make services discoverable and callable. A specification's existence does not establish adoption or dependable transactions. For publishers, the question becomes how original work is credited and paid for when fewer readers visit. For brands, it is whether the agent accurately understands the offer and whose interests guide the recommendation. User preferences, advertising, commissions and platform priorities can point in different directions. Distribution is already a strategic battleground in providers' own materials. OpenAI and Google describe more persistent personal assistance; Microsoft and Anthropic emphasize work and usage patterns. DeepSeek and Qwen bring Chinese model and tooling ecosystems into the picture, while Mistral offers another work-and-coding route. These are strategic directions, not an independently established ranking. Product access, licenses and capabilities vary.
An answer without a visit to its source changes discovery. Pew’s study of US Google browsing found fewer traditional-result clicks on visits with an AI summary. Services may increasingly respond to agent requests. Cloudflare’s open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make them discoverable and callable; a specification does not establish adoption or dependable transactions. Publishers still need credit and payment for original work. Brands need their offers understood accurately. The question is whose interests guide selection: user preferences, advertising, commissions and platform priorities can conflict. Providers describe competing directions: persistent personal assistance at OpenAI and Google; work and usage patterns at Microsoft and Anthropic; Chinese model and tooling ecosystems around DeepSeek and Qwen; another work-and-coding route at Mistral. These are attributed strategies, not an independent ranking. Access, licenses and capabilities vary.
Inline visual: The internet becomes a place agents can act
Visits with a traditional search-result click Pew Research Center Google search visits · US · March 2025 · Google search visits among 900 US adults · March 2025 AI summary present: 8% (emphasized) No AI summary: 15% An observational association, not a causal estimate of global traffic loss. Browsing occurred March 1–31, 2025. Search results were reconstructed April 7–17. The groups can contain different search queries. This measure counts clicks on traditional result links; clicks on links within AI summaries are a separate measure.
Traditional-result clicks: 8% with an AI summary, 15% without Pew Research Center Google search visits · US · March 2025 · Google search visits among 900 US adults · March 2025 AI summary present: 8% (emphasized) No AI summary: 15% An observational association, not a causal estimate of global traffic loss. Browsing occurred March 1–31, 2025. Search results were reconstructed April 7–17. The groups can contain different search queries. This measure counts clicks on traditional result links; clicks on links within AI summaries are a separate measure.
Section: Three questions shape the debate
Selected interpretations, not a representative survey or settled verdict on today’s systems. Names link to sources.
These are attributed perspectives, not a direct debate or a representative survey. They differ on what counts as capability, control and progress. Names link to the original sources.
Inline visual: Three questions shape the debate
Perspectives · affiliations and disclosed interests Ethan Mollick · Wharton professor and author Models may coordinate more work than he expected. Long organizational tasks remain uncertain: experiment, without assuming people are dispensable. Yann LeCun · NYU · AMI Labs executive chairman; ex-Meta Planning needs world models and abstraction that represent consequences. Fei-Fei Li · Stanford HAI · World Labs cofounder and CEO Convincing rendering does not guarantee accurate simulation. Yoshua Bengio · LawZero · leads its safety approach Greater autonomy needs independent safety evidence, accountability and international coordination. Bruce Schneier · Inrupt · user-controlled data interests Hold those configuring and deploying agents responsible; “going rogue” should not obscure human decisions. Daron Acemoglu, David Autor & Simon Johnson · MIT · foundation funding; Autor discloses Google fellowship support Choose systems that expand expertise and create tasks. Replacing work is a different design and institutional choice. Abeba Birhane · Trinity College Dublin · AI Accountability Lab; critical policy perspective Adoption alone is not progress. Demand evidence of benefits and attend to communities’ needs. Simon Willison · Applied-AI practitioner · sponsors and past vendor compensation disclosed Tools and feedback create a working loop that checks results, beyond generating answers.
Where the emphasis differs Can agents plan? Mollick sees more scope in current systems; LeCun emphasizes world models for planning; Li distinguishes convincing renderings from accurate simulations. Ethan Mollick; Yann LeCun; Fei-Fei Li Who carries responsibility? Bengio asks what evidence makes autonomy acceptable; Schneier asks which people remain answerable. These concerns overlap. Yoshua Bengio; Bruce Schneier Who benefits? Efficiency is not a shared definition of progress. Expertise, verified benefits, useful tools, customer control and local access are different tests. Daron Acemoglu, David Autor & Simon Johnson; Abeba Birhane; Simon Willison; Nithin Kamath; Nandan Nilekani Ethan Mollick · Wharton professor and author Models may coordinate more work than he expected. Long organizational tasks remain uncertain: experiment, without assuming people are dispensable. Yann LeCun · NYU · AMI Labs executive chairman; ex-Meta Planning needs world models and abstraction that represent consequences. Fei-Fei Li · Stanford HAI · World Labs cofounder and CEO Convincing rendering does not guarantee accurate simulation. Yoshua Bengio · LawZero · leads its safety approach Greater autonomy needs independent safety evidence, accountability and international coordination. Bruce Schneier · Inrupt · user-controlled data interests Hold those configuring and deploying agents responsible; “going rogue” should not obscure human decisions. Daron Acemoglu, David Autor & Simon Johnson · MIT · foundation funding; Autor discloses Google fellowship support Choose systems that expand expertise and create tasks. Replacing work is a different design and institutional choice. Abeba Birhane · Trinity College Dublin · AI Accountability Lab; critical policy perspective Adoption alone is not progress. Demand evidence of benefits and attend to communities’ needs. Simon Willison · Applied-AI practitioner · sponsors and past vendor compensation disclosed Practical value comes from tools and feedback that let a system check its work. Nithin Kamath · Zerodha cofounder · India; brokerage operator with API access Customers may build their own interfaces while brokers supply the underlying services. He sees an opening for Zerodha, but remains pessimistic about AI’s wider impact. Nandan Nilekani · Infosys cofounder · India; funds AI4Bharat Start with useful applications and access in local languages. Match model size to the task, and build public infrastructure that helps people use it.
Section: Three possible paths: 2029, 2031 and 2036
The following are Atlas scenarios, measured from October 2026. They are ways to test decisions, not predictions with assigned probabilities. Different countries, sectors and customers could experience different combinations. None of these paths requires a particular AGI arrival date. Monitor completed tasks, intervention rates, total cost, repeated use, provider switching and who controls the customer relationship. A polished demonstration or benchmark improvement alone does not settle those questions.
These Atlas scenarios start in October 2026. Different regions and sectors could experience different combinations. They carry no probabilities or assumed AGI date. Watch completed tasks, intervention rates, total cost, provider switching and control of the customer relationship.
Section: What brands and companies should do
Atlas recommendations, not a tested Playbook. Start with dependable information; expand delegation when repeated results justify it.
Removed from this version.
Inline visual: What brands and companies should do
A practical sequence · from October 2026 Now • Keep prices, availability, terms, descriptions and evidence accurate across customer channels. • Publish original expertise and experience. Google supports this; AI-answer inclusion is not guaranteed. • Separate search, identifiable AI referrals, direct and unknown traffic. Measure qualified customers and purchases, not just visibility. • Compare one recurring workflow with today’s process: accepted results, errors, review time and total cost. Name an owner who can stop and correct it. Next 6–24 months • Provide service access where customers or partners need it. Permit stock/order-status checks before order changes. • Test local languages and customer journeys; keep human contact. • Help junior staff build the judgment to supervise the work. Later, when justified • Require verified identity, bounded authority, transaction records and dispute/reversal routes for agent purchasing. • Use protocols supported by actual partners. • Measure major platforms’ effect on margins; preserve alternative customer routes. Optional .md process: goal, inputs, allowed actions, approvals, checks, stop conditions and owner. Connected systems must enforce permissions; the document cannot.
Removed from this version.
Visual: agent-front-door
A new front door to the internet: a personal agent between you and the services you use. Conceptual illustration. A person connects through a personal agent to a network of information and services, with a return path for human control. The Living Atlas · original SVG illustration, AI-assisted · Original Atlas artwork
Direct browsing, left: you go to services. Delegated browsing, right: services feed your agent. A possible shift in the route to information, not a claim that direct visits disappear. Two routes to internet services. On the left a person visits three services directly. On the right services feed a personal agent, which returns a result to the person. The Living Atlas · original SVG illustration, AI-assisted · Original Atlas artwork
Image changed: agent-front-door
Previously recorded image.
New image. Open the version records below to see the retained images.
Visual context: agent-front-door
Previous classification, placement and sources.
Updated classification, placement or sources. See the version records.
Claim: Who benefits is partly a design and institutional choice
Acemoglu, Autor and Johnson emphasize human expertise and new tasks. Birhane calls for evidence of promised benefits and attention to local communities.
Acemoglu, Autor and Johnson prioritize expertise and new tasks; Birhane asks for evidenced benefits. Willison explains the working feedback loop. Kamath sees customer-built interfaces changing brokerage distribution, while Nilekani emphasizes local-language access and useful applications.
Source references: Who benefits is partly a design and institutional choice
Building Pro-Worker Artificial Intelligence · Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgments · https://economics.mit.edu/sites/default/files/2026-03/Building%20Pro-Worker%20Artificial%20Intelligence.pdf AI for Good · Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequences · https://ainowinstitute.org/publications/ai-for-good
Building Pro-Worker Artificial Intelligence · Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgments · https://economics.mit.edu/sites/default/files/2026-03/Building%20Pro-Worker%20Artificial%20Intelligence.pdf AI for Good · Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequences · https://ainowinstitute.org/publications/ai-for-good What is agentic engineering? · Version consulted on 23 October 2026 · Definition of agents, tool loops and verification · https://simonwillison.net/guides/agentic-engineering-patterns/what-is-agentic-engineering/ Welcome to The Back Office · Interview consulted on 23 October 2026 · Episode transcript: AI question, custom interfaces and API access; wider impact · https://zerodha.com/z-connect/business-updates/welcome-to-the-back-office Why the world should stop obsessing over LLMs · Interview consulted on 23 October 2026 · Questions about useful applications, local languages, model size and AI4Bharat · https://restofworld.org/2025/nandan-nilekani-interview-india-ai/
Claim: Prepare reliable information and measure completed work
Atlas recommends accurate product information, original useful content, direct customer relationships and bounded workflow trials before wider delegation.
Removed from this version.
Conditions: Prepare reliable information and measure completed work
Editorial recommendations, not tested Playbooks or a promise of search visibility, ROI or transaction safety.
Removed from this version.
Source references: Prepare reliable information and measure completed work
AI optimization guide · Version consulted on 23 October 2026 · Useful original content, clear information and established search practices · https://developers.google.com/search/docs/fundamentals/ai-optimization-guide Universal Commerce Protocol: specification overview · Version consulted on 23 October 2026 · Profiles, capabilities and version negotiation · https://ucp.dev/2026-08-25/specification/overview/ Generative AI at Work · Version consulted on 23 October 2026 · Abstract and productivity results in the published version · https://doi.org/10.1093/qje/qjae044 We are Changing our Developer Productivity Experiment Design · Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretation · https://metr.org/blog/2026-02-24-uplift-update/
Removed from this version.
Sources used before
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
- AI optimization guide ↗Version consulted on 23 October 2026 · Useful original content, clear information and established search practicesPublished 2026 · recorded in Atlas 23 October 2026
Sources used after
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Welcome to The Back Office ↗Interview consulted on 23 October 2026 · Episode transcript: AI question, custom interfaces and API access; wider impactPublished 22 July 2026 · recorded in Atlas 23 October 2026
- Why the world should stop obsessing over LLMs ↗Interview consulted on 23 October 2026 · Questions about useful applications, local languages, model size and AI4BharatPublished 21 July 2025 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
Available version records (4)
Revision 4 · Editorial change · reviewed
Grouped perspectives by question, added two Indian voices, clarified chart takeaways and illustrated the delegation cycle. Business guidance moves to a companion Playbook.
Answer in this version
An agent can follow an instruction while still relying on a platform's selection, payment and data rules. The next investigation would examine whether people can move their context and permissions between providers without losing practical capabilities.
What remained unresolved
Compare real cross-provider workflows, context export, revoked permissions and recovery from failures. This article has not run those tests.
Takeaway and scope
AI agents could become a new front door to the internet. Their impact will depend on reliable execution, access to services and whose interests they serve.
Evidence through 23 October 2026. Adoption measures have different populations; the future paths are conditional scenarios, not forecasts.
Global adoption needs a defined denominator
The Q2 2026 Microsoft report estimates generative AI use among people aged 15–64 at about 19% worldwide, rounded to the nearest percentage point. Selected economy values use the same report vintage.
Modeled telemetry with adjustments and residual coverage bias; no claim of precise national ranking or agent adoption.
Similar adoption can hide different breadth of use
EIBIS reports generative AI adoption of 37% in EU firms and 36% in US firms. Among AI-using firms, 55% and 81% respectively use it in at least two processes.
2025 survey; value-added weights. Different denominators in the two comparisons; no significance claim for the one-point adoption gap.
More active agents does not establish better outcomes
Microsoft reports 15 times as many active agents in the measured Microsoft 365 ecosystem between March 2025 and March 2026.
Active means at least one day of user-initiated usage or one autonomous run in a rolling 28-day period. The reported ratio does not count successful tasks or global users.
AI summaries and fewer outbound clicks were associated
Pew observed traditional-result clicks on 8% of Google search visits with an AI summary and 15% without one.
US browsing study, March 2025; search results reconstructed in April. Observational association, not a causal global traffic estimate.
AI's productivity effect depends on the work and measurement
A published customer-support study found an average 15% increase in resolved issues per hour. METR's later developer update highlights difficulty estimating current effects.
Different settings and designs, not opposing universal verdicts. The support study concerns human workers, not autonomous agents.
An agent combines a model with tools and feedback
An agent can attempt steps, observe tool results and revise its approach. A system still needs a goal, access boundaries and checks on its output.
The diagram is a conceptual synthesis, not an Atlas product test or a universal implementation.
Several competing product paths are emerging
Announcements and documentation span persistent personal assistance, enterprise workflows, coding agents and efficiency-focused models.
Provider descriptions identify directions; they do not establish a winner, complete availability or comparative reliability.
Mollick, LeCun and Li emphasize different capability questions
Mollick has revised his view of agent organization; LeCun argues for world models and planning; Li distinguishes convincing renderings from accurate simulations.
Attributed assessments, not consensus or a head-to-head experiment. Their roles and interests are disclosed in the source records.
Safety and responsibility need separate questions
Bengio calls for independent safety evidence and oversight; Schneier emphasizes responsibility for how agents are configured and deployed.
Different emphases, not a staged direct debate. No catastrophe probability or incident attribution is established by this article.
Who benefits is partly a design and institutional choice
Acemoglu, Autor and Johnson prioritize expertise and new tasks; Birhane asks for evidenced benefits. Willison explains the working feedback loop. Kamath sees customer-built interfaces changing brokerage distribution, while Nilekani emphasizes local-language access and useful applications.
Conceptual and normative positions, not measured universal effects. Institutional and financial interests are included in source records.
The three paths are conditional Atlas scenarios
User-controlled delegation, platform gatekeeping and uneven automation describe possible combinations of capability, access and control at three, five and ten years.
No probabilities, adoption forecasts or AGI deadlines are estimated. The sources motivate assumptions, not the dates or eventual outcomes.
Explanation in this version
From answering to acting
An assistant can explain a market. An agent preparing a weekly market brief may search, compare, calculate and revise across tools. The change is delegated action between your instruction and the final response.
A useful personal agent also needs relevant memory, service access, a budget, checks and permission boundaries. Memory must allow correction and deletion: a preference stored six months ago may no longer be yours.
Conceptual workflow Act, check and return control
- 1. Set the goalName the result, owner, budget and permitted actions.
- 2. Use relevant contextRead approved documents and correct outdated memory.
- 3. Act and checkUse tools; verify the result against the goal.
- 4. Return controlShow the result and log; ask before client delivery.
Stop when checks fail
Illustrative brief-preparation cycle, not an Atlas test. Connected systems must enforce permissions.
A global transition, with uneven access
There is no single percentage for “how much the world uses AI.” Surveys and telemetry measure different populations. One consistent methodology can show variation without removing its coverage gaps.
Language, connectivity, mobile access, available services and payment systems shape which tasks are practical. High model capability in one market does not establish broad access elsewhere. General AI use also does not measure autonomous-agent adoption.
EU and US: adoption is only the first step
A common survey makes the EU–US comparison more useful. The European Investment Bank’s 2025 results show similar generative AI adoption, but a larger difference in breadth. The panels have different denominators: adopting AI and using it across processes are separate questions.
Count useful outcomes, not just agents
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools.
Judge a workflow by acceptable results and total cost, including review, corrections, failed runs and integration—not the number of drafts it generates.
Vendor data · Microsoft Microsoft reports 15× as many active agents in one year
15×as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft.
Agent activity is not a count of people, successful outcomes or global productivity.
Definition & scope
At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
The internet becomes a place agents can act
An answer without a visit to its source changes discovery. Pew’s study of US Google browsing found fewer traditional-result clicks on visits with an AI summary.
Services may increasingly respond to agent requests. Cloudflare’s open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make them discoverable and callable; a specification does not establish adoption or dependable transactions.
Publishers still need credit and payment for original work. Brands need their offers understood accurately. The question is whose interests guide selection: user preferences, advertising, commissions and platform priorities can conflict.
Providers describe competing directions: persistent personal assistance at OpenAI and Google; work and usage patterns at Microsoft and Anthropic; Chinese model and tooling ecosystems around DeepSeek and Qwen; another work-and-coding route at Mistral. These are attributed strategies, not an independent ranking. Access, licenses and capabilities vary.
Three questions shape the debate
These are attributed perspectives, not a direct debate or a representative survey. They differ on what counts as capability, control and progress. Names link to the original sources.
Where the emphasis differs Can agents plan?
Mollick sees more scope in current systems; LeCun emphasizes world models for planning; Li distinguishes convincing renderings from accurate simulations.
Ethan Mollick
Wharton professor and author
Models may coordinate more work than he expected. Long organizational tasks remain uncertain: experiment, without assuming people are dispensable.
Yann LeCun
NYU · AMI Labs executive chairman; ex-Meta
Planning needs world models and abstraction that represent consequences.
Fei-Fei Li
Stanford HAI · World Labs cofounder and CEO
Convincing rendering does not guarantee accurate simulation.
Who carries responsibility?
Bengio asks what evidence makes autonomy acceptable; Schneier asks which people remain answerable. These concerns overlap.
Yoshua Bengio
LawZero · leads its safety approach
Greater autonomy needs independent safety evidence, accountability and international coordination.
Bruce Schneier
Inrupt · user-controlled data interests
Hold those configuring and deploying agents responsible; “going rogue” should not obscure human decisions.
Who benefits?
Efficiency is not a shared definition of progress. Expertise, verified benefits, useful tools, customer control and local access are different tests.
Daron Acemoglu, David Autor & Simon Johnson
MIT · foundation funding; Autor discloses Google fellowship support
Choose systems that expand expertise and create tasks. Replacing work is a different design and institutional choice.
Abeba Birhane
Trinity College Dublin · AI Accountability Lab; critical policy perspective
Adoption alone is not progress. Demand evidence of benefits and attend to communities’ needs.
Simon Willison
Applied-AI practitioner · sponsors and past vendor compensation disclosed
Practical value comes from tools and feedback that let a system check its work.
Nithin Kamath
Zerodha cofounder · India; brokerage operator with API access
Customers may build their own interfaces while brokers supply the underlying services. He sees an opening for Zerodha, but remains pessimistic about AI’s wider impact.
Nandan Nilekani
Infosys cofounder · India; funds AI4Bharat
Start with useful applications and access in local languages. Match model size to the task, and build public infrastructure that helps people use it.
Three possible paths: 2029, 2031 and 2036
These Atlas scenarios start in October 2026. Different regions and sectors could experience different combinations. They carry no probabilities or assumed AGI date. Watch completed tasks, intervention rates, total cost, provider switching and control of the customer relationship.
Atlas scenarios · 3, 5 and 10 years from October 2026 User-controlled delegation
- 2029
- Useful tasks work across services.
- 2031
- Recurring work uses portable context.
- 2036
- Personal agents become a common front door to services.
Watch for: Dependable results, usable permissions and easy switching support this path; lock-in and heavy rework weaken it.
Platform gatekeeping
- 2029
- Integrated ecosystems offer the easiest experience.
- 2031
- More discovery and transactions pass through their agents.
- 2036
- A few intermediaries strongly influence customer access and creator income.
Watch for: Concentrated distribution supports this path; easy switching and durable direct relationships weaken it.
Uneven automation
- 2029
- Bounded tasks improve; long chains still need intervention.
- 2031
- Controlled environments progress faster than open-web work.
- 2036
- Agents coexist with apps and human services.
Watch for: Repeated, economical success on long tasks across organizations and languages would weaken this path.
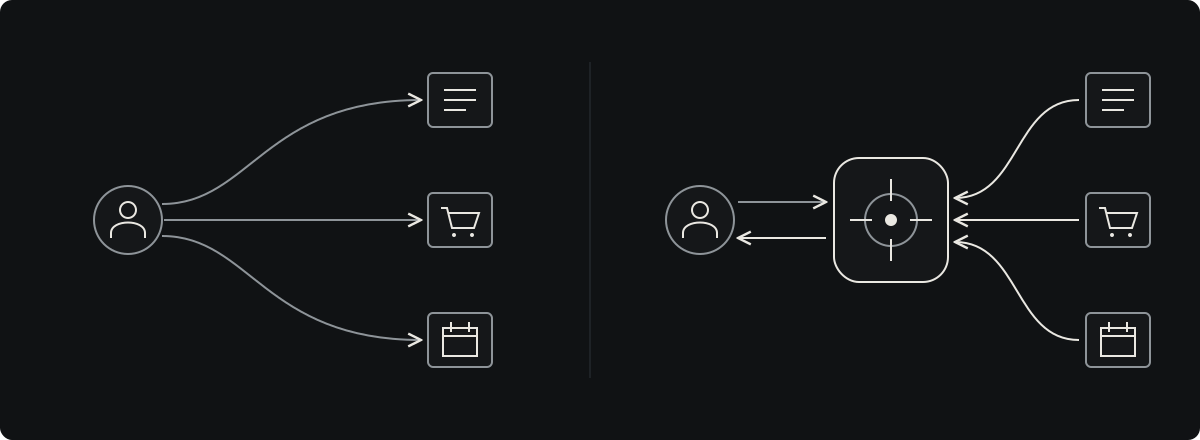
Schematic · not measured data Direct browsing, left: you go to services. Delegated browsing, right: services feed your agent. A possible shift in the route to information, not a claim that direct visits disappear.
Sources in this version
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Welcome to The Back Office ↗Interview consulted on 23 October 2026 · Episode transcript: AI question, custom interfaces and API access; wider impactPublished 22 July 2026 · recorded in Atlas 23 October 2026
- Why the world should stop obsessing over LLMs ↗Interview consulted on 23 October 2026 · Questions about useful applications, local languages, model size and AI4BharatPublished 21 July 2025 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
Revision 3 · Editorial change · reviewed
Highlighted the key chart comparisons and thinned the scale guides. Reorganized the individual perspectives and business actions into compact, sourced cards and time-horizon columns. Evidence and numeric values are unchanged.
Answer in this version
An agent can follow an instruction while still relying on a platform's selection, payment and data rules. The next investigation would examine whether people can move their context and permissions between providers without losing practical capabilities.
What remained unresolved
Compare real cross-provider workflows, context export, revoked permissions and recovery from failures. This article has not run those tests.
Takeaway and scope
AI agents could become a new front door to the internet. Their impact will depend on reliable execution, access to services and whose interests they serve.
Evidence through 23 October 2026. Adoption measures have different populations; the future paths are conditional scenarios, not forecasts.
Global adoption needs a defined denominator
The Q2 2026 Microsoft report estimates generative AI use among people aged 15–64 at about 19% worldwide, rounded to the nearest percentage point. Selected economy values use the same report vintage.
Modeled telemetry with adjustments and residual coverage bias; no claim of precise national ranking or agent adoption.
Similar adoption can hide different breadth of use
EIBIS reports generative AI adoption of 37% in EU firms and 36% in US firms. Among AI-using firms, 55% and 81% respectively use it in at least two processes.
2025 survey; value-added weights. Different denominators in the two comparisons; no significance claim for the one-point adoption gap.
More active agents does not establish better outcomes
Microsoft reports 15 times as many active agents in the measured Microsoft 365 ecosystem between March 2025 and March 2026.
Active means at least one day of user-initiated usage or one autonomous run in a rolling 28-day period. The reported ratio does not count successful tasks or global users.
AI summaries and fewer outbound clicks were associated
Pew observed traditional-result clicks on 8% of Google search visits with an AI summary and 15% without one.
US browsing study, March 2025; search results reconstructed in April. Observational association, not a causal global traffic estimate.
AI's productivity effect depends on the work and measurement
A published customer-support study found an average 15% increase in resolved issues per hour. METR's later developer update highlights difficulty estimating current effects.
Different settings and designs, not opposing universal verdicts. The support study concerns human workers, not autonomous agents.
An agent combines a model with tools and feedback
An agent can attempt steps, observe tool results and revise its approach. A system still needs a goal, access boundaries and checks on its output.
The diagram is a conceptual synthesis, not an Atlas product test or a universal implementation.
Several competing product paths are emerging
Announcements and documentation span persistent personal assistance, enterprise workflows, coding agents and efficiency-focused models.
Provider descriptions identify directions; they do not establish a winner, complete availability or comparative reliability.
Mollick, LeCun and Li emphasize different capability questions
Mollick has revised his view of agent organization; LeCun argues for world models and planning; Li distinguishes convincing renderings from accurate simulations.
Attributed assessments, not consensus or a head-to-head experiment. Their roles and interests are disclosed in the source records.
Safety and responsibility need separate questions
Bengio calls for independent safety evidence and oversight; Schneier emphasizes responsibility for how agents are configured and deployed.
Different emphases, not a staged direct debate. No catastrophe probability or incident attribution is established by this article.
Who benefits is partly a design and institutional choice
Acemoglu, Autor and Johnson emphasize human expertise and new tasks. Birhane calls for evidence of promised benefits and attention to local communities.
Conceptual and normative positions, not measured universal effects. Institutional and financial interests are included in source records.
The three paths are conditional Atlas scenarios
User-controlled delegation, platform gatekeeping and uneven automation describe possible combinations of capability, access and control at three, five and ten years.
No probabilities, adoption forecasts or AGI deadlines are estimated. The sources motivate assumptions, not the dates or eventual outcomes.
Prepare reliable information and measure completed work
Atlas recommends accurate product information, original useful content, direct customer relationships and bounded workflow trials before wider delegation.
Editorial recommendations, not tested Playbooks or a promise of search visibility, ROI or transaction safety.
Explanation in this version
From answering to acting
Ask an assistant to explain a market and it returns information. Ask an agent to prepare a weekly market brief and it may search, read, compare, calculate and revise a draft across several tools. The important change is delegated action: the system can do work between your instructions and its final response.
A useful personal agent would need more than a capable model. It would need relevant memory, access to the right services, a budget, a way to check results and a clear account of what it may do without asking. Memory would need correction and deletion as well as recall. A preference stored six months ago is not automatically your preference today.
Conceptual workflow A personal agent needs a controlled working loop
- Set the goalName the result, owner, budget and permitted actions.
- Use relevant contextRead approved documents and correct outdated memory.
- Act and checkUse tools, inspect the result and stop when checks fail.
- Return controlShow the result and action log; ask before sending it to a client.
Illustrative meeting-brief workflow; not an Atlas test. Permissions must be enforced by the connected systems.
A global transition, with uneven access
There is no single trustworthy percentage for “how much the world uses AI.” Surveys ask different questions; telemetry sees different users; companies and individuals are different populations. One consistent methodology can reveal variation without resolving all those differences.
An agent future built around an English-speaking office worker is only one future. Language, mobile access, service availability, connectivity and local payment systems can change which tasks are practical. High model capability in one market does not establish broad access in another. Nor does a country's adoption share tell us how many people use agents autonomously.
EU and US: adoption is only the first step
A common survey is more informative than comparing unrelated national statistics. The European Investment Bank's 2025 results put reported generative AI adoption at similar levels in the EU and US, while revealing a larger difference in how broadly AI is used.
The panels have different denominators. They suggest why “we have adopted AI” is an incomplete management metric: it says little about what work has changed or whether the result improved.
Count useful outcomes, not just agents
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools.
The practical question is whether a workflow produces more acceptable work at a sustainable total cost. Include review, corrections, failed runs and integration work. A system that generates ten drafts but requires extensive repair has not necessarily outperformed one careful human draft.
Vendor data · Microsoft Activity inside one provider’s ecosystem
15×as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft.
Agent activity is not a count of people, successful outcomes or global productivity.
Definition & scope
At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
The internet becomes a place agents can act
If an agent answers a question without sending the person to the source, the economics of discovery change. Pew's study of US Google browsing found fewer traditional-result clicks on visits with an AI summary.
Sites can still supply the information, services and relationships behind an agent's answer. What may change is the route to them: from a person choosing links to a system selecting sources and requesting actions. Cloudflare's open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make services discoverable and callable. A specification's existence does not establish adoption or dependable transactions.
For publishers, the question becomes how original work is credited and paid for when fewer readers visit. For brands, it is whether the agent accurately understands the offer and whose interests guide the recommendation. User preferences, advertising, commissions and platform priorities can point in different directions.
Distribution is already a strategic battleground in providers' own materials. OpenAI and Google describe more persistent personal assistance; Microsoft and Anthropic emphasize work and usage patterns. DeepSeek and Qwen bring Chinese model and tooling ecosystems into the picture, while Mistral offers another work-and-coding route. These are strategic directions, not an independently established ranking. Product access, licenses and capabilities vary.
What prominent voices disagree about
Selected interpretations, not a representative survey or settled verdict on today’s systems. Names link to sources.
Perspectives · affiliations and disclosed interests Ethan Mollick
Wharton professor and author
Models may coordinate more work than he expected. Long organizational tasks remain uncertain: experiment, without assuming people are dispensable.
Yann LeCun
NYU · AMI Labs executive chairman; ex-Meta
Planning needs world models and abstraction that represent consequences.
Fei-Fei Li
Stanford HAI · World Labs cofounder and CEO
Convincing rendering does not guarantee accurate simulation.
Yoshua Bengio
LawZero · leads its safety approach
Greater autonomy needs independent safety evidence, accountability and international coordination.
Bruce Schneier
Inrupt · user-controlled data interests
Hold those configuring and deploying agents responsible; “going rogue” should not obscure human decisions.
Daron Acemoglu, David Autor & Simon Johnson
MIT · foundation funding; Autor discloses Google fellowship support
Choose systems that expand expertise and create tasks. Replacing work is a different design and institutional choice.
Abeba Birhane
Trinity College Dublin · AI Accountability Lab; critical policy perspective
Adoption alone is not progress. Demand evidence of benefits and attend to communities’ needs.
Simon Willison
Applied-AI practitioner · sponsors and past vendor compensation disclosed
Tools and feedback create a working loop that checks results, beyond generating answers.
Three possible paths: 2029, 2031 and 2036
The following are Atlas scenarios, measured from October 2026. They are ways to test decisions, not predictions with assigned probabilities. Different countries, sectors and customers could experience different combinations.
None of these paths requires a particular AGI arrival date. Monitor completed tasks, intervention rates, total cost, repeated use, provider switching and who controls the customer relationship. A polished demonstration or benchmark improvement alone does not settle those questions.
Atlas scenarios · 3, 5 and 10 years from October 2026 User-controlled delegation
- 2029
- Useful tasks work across services.
- 2031
- Recurring work uses portable context.
- 2036
- Personal agents become a common front door to services.
Watch for: Dependable results, usable permissions and easy switching support this path; lock-in and heavy rework weaken it.
Platform gatekeeping
- 2029
- Integrated ecosystems offer the easiest experience.
- 2031
- More discovery and transactions pass through their agents.
- 2036
- A few intermediaries strongly influence customer access and creator income.
Watch for: Concentrated distribution supports this path; easy switching and durable direct relationships weaken it.
Uneven automation
- 2029
- Bounded tasks improve; long chains still need intervention.
- 2031
- Controlled environments progress faster than open-web work.
- 2036
- Agents coexist with apps and human services.
Watch for: Repeated, economical success on long tasks across organizations and languages would weaken this path.
What brands and companies should do
Atlas recommendations, not a tested Playbook. Start with dependable information; expand delegation when repeated results justify it.
A practical sequence · from October 2026 Now
- Keep prices, availability, terms, descriptions and evidence accurate across customer channels.
- Publish original expertise and experience. Google supports this; AI-answer inclusion is not guaranteed.
- Separate search, identifiable AI referrals, direct and unknown traffic. Measure qualified customers and purchases, not just visibility.
- Compare one recurring workflow with today’s process: accepted results, errors, review time and total cost. Name an owner who can stop and correct it.
Next 6–24 months
- Provide service access where customers or partners need it. Permit stock/order-status checks before order changes.
- Test local languages and customer journeys; keep human contact.
- Help junior staff build the judgment to supervise the work.
Later, when justified
- Require verified identity, bounded authority, transaction records and dispute/reversal routes for agent purchasing.
- Use protocols supported by actual partners.
- Measure major platforms’ effect on margins; preserve alternative customer routes.
Optional .md process: goal, inputs, allowed actions, approvals, checks, stop conditions and owner. Connected systems must enforce permissions; the document cannot.
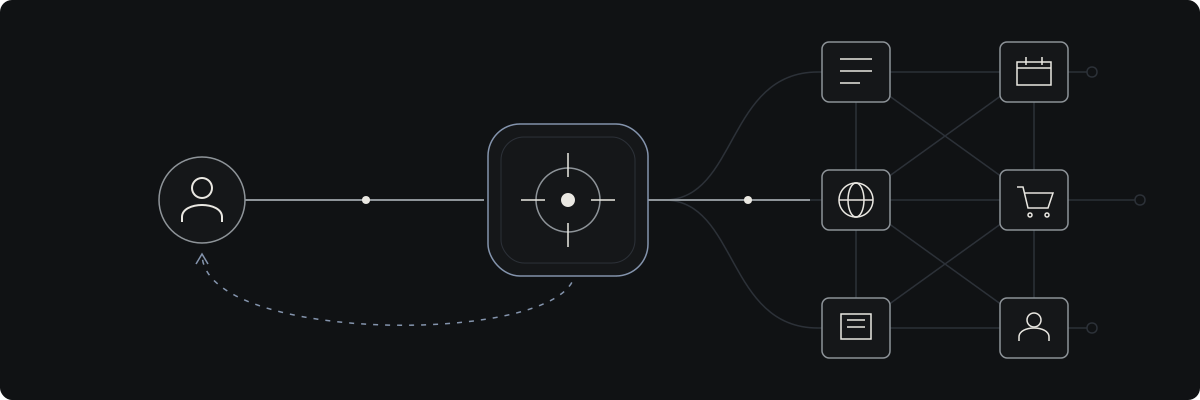
Illustration A new front door to the internet: a personal agent between you and the services you use. Conceptual illustration.
Sources in this version
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
- AI optimization guide ↗Version consulted on 23 October 2026 · Useful original content, clear information and established search practicesPublished 2026 · recorded in Atlas 23 October 2026
Revision 2 · Editorial change · reviewed
Replaced raster figures with readable native charts, data tables and scenario text; added an Atlas SVG cover. Rounded displayed percentages and made data origins explicit. Underlying findings are unchanged.
Answer in this version
An agent can follow an instruction while still relying on a platform's selection, payment and data rules. The next investigation would examine whether people can move their context and permissions between providers without losing practical capabilities.
What remained unresolved
Compare real cross-provider workflows, context export, revoked permissions and recovery from failures. This article has not run those tests.
Takeaway and scope
AI agents could become a new front door to the internet. Their impact will depend on reliable execution, access to services and whose interests they serve.
Evidence through 23 October 2026. Adoption measures have different populations; the future paths are conditional scenarios, not forecasts.
Global adoption needs a defined denominator
The Q2 2026 Microsoft report estimates generative AI use among people aged 15–64 at about 19% worldwide, rounded to the nearest percentage point. Selected economy values use the same report vintage.
Modeled telemetry with adjustments and residual coverage bias; no claim of precise national ranking or agent adoption.
Similar adoption can hide different breadth of use
EIBIS reports generative AI adoption of 37% in EU firms and 36% in US firms. Among AI-using firms, 55% and 81% respectively use it in at least two processes.
2025 survey; value-added weights. Different denominators in the two comparisons; no significance claim for the one-point adoption gap.
More active agents does not establish better outcomes
Microsoft reports 15 times as many active agents in the measured Microsoft 365 ecosystem between March 2025 and March 2026.
Active means at least one day of user-initiated usage or one autonomous run in a rolling 28-day period. The reported ratio does not count successful tasks or global users.
AI summaries and fewer outbound clicks were associated
Pew observed traditional-result clicks on 8% of Google search visits with an AI summary and 15% without one.
US browsing study, March 2025; search results reconstructed in April. Observational association, not a causal global traffic estimate.
AI's productivity effect depends on the work and measurement
A published customer-support study found an average 15% increase in resolved issues per hour. METR's later developer update highlights difficulty estimating current effects.
Different settings and designs, not opposing universal verdicts. The support study concerns human workers, not autonomous agents.
An agent combines a model with tools and feedback
An agent can attempt steps, observe tool results and revise its approach. A system still needs a goal, access boundaries and checks on its output.
The diagram is a conceptual synthesis, not an Atlas product test or a universal implementation.
Several competing product paths are emerging
Announcements and documentation span persistent personal assistance, enterprise workflows, coding agents and efficiency-focused models.
Provider descriptions identify directions; they do not establish a winner, complete availability or comparative reliability.
Mollick, LeCun and Li emphasize different capability questions
Mollick has revised his view of agent organization; LeCun argues for world models and planning; Li distinguishes convincing renderings from accurate simulations.
Attributed assessments, not consensus or a head-to-head experiment. Their roles and interests are disclosed in the source records.
Safety and responsibility need separate questions
Bengio calls for independent safety evidence and oversight; Schneier emphasizes responsibility for how agents are configured and deployed.
Different emphases, not a staged direct debate. No catastrophe probability or incident attribution is established by this article.
Who benefits is partly a design and institutional choice
Acemoglu, Autor and Johnson emphasize human expertise and new tasks. Birhane calls for evidence of promised benefits and attention to local communities.
Conceptual and normative positions, not measured universal effects. Institutional and financial interests are included in source records.
The three paths are conditional Atlas scenarios
User-controlled delegation, platform gatekeeping and uneven automation describe possible combinations of capability, access and control at three, five and ten years.
No probabilities, adoption forecasts or AGI deadlines are estimated. The sources motivate assumptions, not the dates or eventual outcomes.
Prepare reliable information and measure completed work
Atlas recommends accurate product information, original useful content, direct customer relationships and bounded workflow trials before wider delegation.
Editorial recommendations, not tested Playbooks or a promise of search visibility, ROI or transaction safety.
Explanation in this version
From answering to acting
Ask an assistant to explain a market and it returns information. Ask an agent to prepare a weekly market brief and it may search, read, compare, calculate and revise a draft across several tools. The important change is delegated action: the system can do work between your instructions and its final response.
A useful personal agent would need more than a capable model. It would need relevant memory, access to the right services, a budget, a way to check results and a clear account of what it may do without asking. Memory would need correction and deletion as well as recall. A preference stored six months ago is not automatically your preference today.
Imagine a meeting brief assembled from approved documents. Simon Willison's account of agentic engineering explains why tools and feedback matter: a system that can check a result has a different working loop from one that only generates an answer.
Conceptual workflow A personal agent needs a controlled working loop
- Set the goalName the result, owner, budget and permitted actions.
- Use relevant contextRead approved documents and correct outdated memory.
- Act and checkUse tools, inspect the result and stop when checks fail.
- Return controlShow the result and action log; ask before sending it to a client.
Illustrative meeting-brief workflow; not an Atlas test. Permissions must be enforced by the connected systems.
A global transition, with uneven access
There is no single trustworthy percentage for “how much the world uses AI.” Surveys ask different questions; telemetry sees different users; companies and individuals are different populations. One consistent methodology can reveal variation without resolving all those differences.
An agent future built around an English-speaking office worker is only one future. Language, mobile access, service availability, connectivity and local payment systems can change which tasks are practical. High model capability in one market does not establish broad access in another. Nor does a country's adoption share tell us how many people use agents autonomously.
EU and US: adoption is only the first step
A common survey is more informative than comparing unrelated national statistics. The European Investment Bank's 2025 results put reported generative AI adoption at similar levels in the EU and US, while revealing a larger difference in how broadly AI is used.
The panels have different denominators. They suggest why “we have adopted AI” is an incomplete management metric: it says little about what work has changed or whether the result improved.
Count useful outcomes, not just agents
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools.
The practical question is whether a workflow produces more acceptable work at a sustainable total cost. Include review, corrections, failed runs and integration work. A system that generates ten drafts but requires extensive repair has not necessarily outperformed one careful human draft.
Vendor data · Microsoft Activity inside one provider’s ecosystem
15×as many active agents in the measured Microsoft 365 ecosystem in March 2026 as in March 2025, according to Microsoft.
Agent activity is not a count of people, successful outcomes or global productivity.
Definition & scope
At least one day of user-initiated usage or at least one autonomous run in a rolling 28-day period. Scope: Microsoft 365 Copilot Agents platform and SharePoint agents; Agent Builder and Microsoft 365 Agents Toolkit; all countries and customer segments in the reported telemetry. The source reports a ratio; no absolute count is supplied in this extract.
The internet becomes a place agents can act
If an agent answers a question without sending the person to the source, the economics of discovery change. Pew's study of US Google browsing found fewer traditional-result clicks on visits with an AI summary.
Sites can still supply the information, services and relationships behind an agent's answer. What may change is the route to them: from a person choosing links to a system selecting sources and requesting actions. Cloudflare's open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make services discoverable and callable. A specification's existence does not establish adoption or dependable transactions.
For publishers, the question becomes how original work is credited and paid for when fewer readers visit. For brands, it is whether the agent accurately understands the offer and whose interests guide the recommendation. User preferences, advertising, commissions and platform priorities can point in different directions.
Distribution is already a strategic battleground in providers' own materials. OpenAI and Google describe more persistent personal assistance; Microsoft and Anthropic emphasize work and usage patterns. DeepSeek and Qwen bring Chinese model and tooling ecosystems into the picture, while Mistral offers another work-and-coding route. These are strategic directions, not an independently established ranking. Product access, licenses and capabilities vary.
What prominent voices disagree about
Ethan Mollick's October 2026 essay revises his earlier view of agent organization: he now thinks models can do more of the coordination that he previously expected humans to design. He still leaves open how well this works for long, ordinary organizational tasks. His argument supports experimentation, not a claim that human work has already become dispensable.
Yann LeCun puts more weight on the architecture needed for planning and understanding consequences, arguing for world models and abstraction. Fei-Fei Li stresses a related distinction: a convincing rendering is not necessarily an accurate simulation. These are research judgments, not a settled verdict on what today's systems can achieve.
Yoshua Bengio argues for independent safety evidence, accountability and international coordination as systems gain more power to act. Bruce Schneier draws attention to the humans and organizations configuring and deploying those systems. Responsibility should not disappear behind a story about a machine “going rogue.”
Daron Acemoglu, David Autor and Simon Johnson ask what kind of AI we choose to build: systems that expand human expertise and create new tasks have different implications from systems designed mainly to replace existing work. Abeba Birhane challenges a complementary assumption—that wider adoption automatically means social progress. She calls for evidence of benefits and attention to what communities actually need.
These voices are not disinterested or interchangeable. Mollick is an academic and author; LeCun, Li and Bengio lead or help lead AI organizations; Schneier works with Inrupt. Willison discloses sponsors, applied-AI work and past vendor compensation. The pro-worker paper includes funding disclosures. Birhane's accountability research has a critical policy perspective. Their arguments should be assessed on their merits, with those positions visible. This selection is not a representative survey of world opinion.
Three possible paths: 2029, 2031 and 2036
The following are Atlas scenarios, measured from October 2026. They are ways to test decisions, not predictions with assigned probabilities. Different countries, sectors and customers could experience different combinations.
None of these paths requires a particular AGI arrival date. Monitor completed tasks, intervention rates, total cost, repeated use, provider switching and who controls the customer relationship. A polished demonstration or benchmark improvement alone does not settle those questions.
Atlas scenarios · 3, 5 and 10 years from October 2026 User-controlled delegation
- 2029
- Useful tasks work across services.
- 2031
- Recurring work uses portable context.
- 2036
- Personal agents become a common front door to services.
Watch for: Dependable results, usable permissions and easy switching support this path; lock-in and heavy rework weaken it.
Platform gatekeeping
- 2029
- Integrated ecosystems offer the easiest experience.
- 2031
- More discovery and transactions pass through their agents.
- 2036
- A few intermediaries strongly influence customer access and creator income.
Watch for: Concentrated distribution supports this path; easy switching and durable direct relationships weaken it.
Uneven automation
- 2029
- Bounded tasks improve; long chains still need intervention.
- 2031
- Controlled environments progress faster than open-web work.
- 2036
- Agents coexist with apps and human services.
Watch for: Repeated, economical success on long tasks across organizations and languages would weaken this path.
What brands and companies should do
Now: make the offer dependable. Keep prices, availability, terms, product descriptions and supporting evidence accurate across the channels customers use. Publish material grounded in your own expertise and experience. Google's guidance supports useful original content and clear information; it does not guarantee inclusion in an AI answer.
Now: establish a baseline. Distinguish search traffic, identifiable AI referrals, direct visits and unknown attribution. Track qualified customers and completed purchases as well as visibility. Test one recurring workflow against the current process, measuring acceptable results, errors, review time and total cost. Give it an owner who can stop it and correct mistakes.
Over the next 6–24 months: prepare controlled service access where customers or partners need it. Let an agent check stock or order status before allowing it to change an order. Test local languages and customer journeys. Keep direct human contact available, and plan how junior staff continue to build the judgment needed to supervise the work.
Later: expand delegation when repeated results justify it. Agent-mediated purchasing needs verified identity, bounded authority, transaction records and a route to dispute or reverse mistakes. Consider protocols where actual partners support them. If one platform becomes a major source of customers, measure its effect on margins and preserve alternative routes.
Readable process files can help. A Markdown document can describe the goal, inputs, allowed actions, approval points, checks, stop conditions and responsible owner. But .md is an optional format for instructions, not an enforcement mechanism. The connected systems must apply the permissions. These are editorial recommendations, not an Atlas-tested Playbook.
Illustration A new front door to the internet: a personal agent between you and the services you use. Conceptual illustration.
Sources in this version
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
- AI optimization guide ↗Version consulted on 23 October 2026 · Useful original content, clear information and established search practicesPublished 2026 · recorded in Atlas 23 October 2026
Revision 1 · First recorded version · reviewed
A global, source-backed explanation of agents, the changing internet and three conditional futures, with six original figures.
Answer in this version
An agent can follow an instruction while still relying on a platform's selection, payment and data rules. The next investigation would examine whether people can move their context and permissions between providers without losing practical capabilities.
What remained unresolved
Compare real cross-provider workflows, context export, revoked permissions and recovery from failures. This article has not run those tests.
Takeaway and scope
AI agents could become a new front door to the internet. Their impact will depend on reliable execution, access to services and whose interests they serve.
Evidence through 23 October 2026. Adoption measures have different populations; the future paths are conditional scenarios, not forecasts.
Global adoption needs a defined denominator
The Q2 2026 Microsoft report estimates generative AI use among people aged 15–64 at 18.8% worldwide. Selected economy values use the same report vintage.
Modeled telemetry with adjustments and residual coverage bias; no claim of precise national ranking or agent adoption.
Similar adoption can hide different breadth of use
EIBIS reports generative AI adoption of 37% in EU firms and 36% in US firms. Among AI-using firms, 55% and 81% respectively use it in at least two processes.
2025 survey; value-added weights. Different denominators in the two comparisons; no significance claim for the one-point adoption gap.
More active agents does not establish better outcomes
Microsoft reports 15 times as many active agents in the measured Microsoft 365 ecosystem between March 2025 and March 2026.
Index 100 to 1,500 is an Atlas calculation from the reported ratio. Activity is not a count of successful tasks or global users.
AI summaries and fewer outbound clicks were associated
Pew observed traditional-result clicks on 8% of Google search visits with an AI summary and 15% without one.
US browsing study, March 2025; search results reconstructed in April. Observational association, not a causal global traffic estimate.
AI's productivity effect depends on the work and measurement
A published customer-support study found an average 15% increase in resolved issues per hour. METR's later developer update highlights difficulty estimating current effects.
Different settings and designs, not opposing universal verdicts. The support study concerns human workers, not autonomous agents.
An agent combines a model with tools and feedback
An agent can attempt steps, observe tool results and revise its approach. A system still needs a goal, access boundaries and checks on its output.
The diagram is a conceptual synthesis, not an Atlas product test or a universal implementation.
Several competing product paths are emerging
Announcements and documentation span persistent personal assistance, enterprise workflows, coding agents and efficiency-focused models.
Provider descriptions identify directions; they do not establish a winner, complete availability or comparative reliability.
Mollick, LeCun and Li emphasize different capability questions
Mollick has revised his view of agent organization; LeCun argues for world models and planning; Li distinguishes convincing renderings from accurate simulations.
Attributed assessments, not consensus or a head-to-head experiment. Their roles and interests are disclosed in the source records.
Safety and responsibility need separate questions
Bengio calls for independent safety evidence and oversight; Schneier emphasizes responsibility for how agents are configured and deployed.
Different emphases, not a staged direct debate. No catastrophe probability or incident attribution is established by this article.
Who benefits is partly a design and institutional choice
Acemoglu, Autor and Johnson emphasize human expertise and new tasks. Birhane calls for evidence of promised benefits and attention to local communities.
Conceptual and normative positions, not measured universal effects. Institutional and financial interests are included in source records.
The three paths are conditional Atlas scenarios
User-controlled delegation, platform gatekeeping and uneven automation describe possible combinations of capability, access and control at three, five and ten years.
No probabilities, adoption forecasts or AGI deadlines are estimated. The sources motivate assumptions, not the dates or eventual outcomes.
Prepare reliable information and measure completed work
Atlas recommends accurate product information, original useful content, direct customer relationships and bounded workflow trials before wider delegation.
Editorial recommendations, not tested Playbooks or a promise of search visibility, ROI or transaction safety.
Explanation in this version
From answering to acting
Ask an assistant to explain a market and it returns information. Ask an agent to prepare a weekly market brief and it may search, read, compare, calculate and revise a draft across several tools. The important change is delegated action: the system can do work between your instructions and its final response.
A useful personal agent would need more than a capable model. It would need relevant memory, access to the right services, a budget, a way to check results and a clear account of what it may do without asking. Memory would need correction and deletion as well as recall. A preference stored six months ago is not automatically your preference today.
Imagine a meeting brief assembled from approved documents. The agent can draft the analysis and identify uncertainty; sending it to a client is a separate permission. This is an illustrative workflow, not an Atlas test. Simon Willison's account of agentic engineering explains why tools and feedback matter: a system that can check a result has a different working loop from one that only generates an answer.
A global transition, with uneven access
There is no single trustworthy percentage for “how much the world uses AI.” Surveys ask different questions; telemetry sees different users; companies and individuals are different populations. The chart below uses one consistent Microsoft methodology for selected economies. Its estimated world share rose from 16.3% in H2 2025 to 18.8% in Q2 2026.
These are adjusted estimates for people aged 15–64, not a census. The method remains sensitive to desktop access and the people Microsoft can observe. Its 147-economy coverage is useful, but the decimal places should not imply perfect precision. The selected countries illustrate geographic variation; they do not stand for entire continents. Microsoft notes that several widely used domestic Chinese tools are missing from its coverage; including them would be expected to raise the China estimate.
An agent future built around an English-speaking office worker is only one future. Language, mobile access, service availability, connectivity and local payment systems can change which tasks are practical. High model capability in one market does not establish broad access in another. Nor does a country's adoption share tell us how many people use agents autonomously.
EU and US: adoption is only the first step
A common survey is more informative than comparing unrelated national statistics. The European Investment Bank's 2025 survey reports generative AI use at 37% for EU firms and 36% for US firms. Those results use value-added weights; they are not a simple count of all businesses.
The larger distinction is breadth. Among AI-using firms, 55% in the EU and 81% in the US report use in at least two processes. The panels have different denominators. They suggest why “we have adopted AI” is an incomplete management metric: it says little about what work has changed or whether the result improved.
Count useful outcomes, not just agents
Microsoft reports a fifteenfold rise in active agents within its measured Microsoft 365 ecosystem from March 2025 to March 2026. An agent can qualify as active through limited user-initiated activity or a single autonomous run in a 28-day window. That is evidence of activity inside one ecosystem, not fifteenfold growth in global productivity.
Useful effects are possible. A published study of 5,172 customer-support workers found an average 15% increase in issues resolved per hour after AI assistance was introduced, with different effects across workers. Here, “agents” means people in support roles. Conversely, METR's developer research update explains why selection and time-measurement problems limit conclusions about current coding tools.
The practical question is whether a workflow produces more acceptable work at a sustainable total cost. Include review, corrections, failed runs and integration work. A system that generates ten drafts but requires extensive repair has not necessarily outperformed one careful human draft.
The internet becomes a place agents can act
If an agent answers a question without sending the person to the source, the economics of discovery change. In Pew's study of US Google browsing, traditional-result links received clicks on 8% of visits with an AI summary and 15% without. This is an association from March 2025, not proof that AI caused a particular traffic loss everywhere.
Sites can still supply the information, services and relationships behind an agent's answer. What may change is the route to them: from a person choosing links to a system selecting sources and requesting actions. Cloudflare's open-agent internet proposal and the Universal Commerce Protocol illustrate attempts to make services discoverable and callable. A specification's existence does not establish adoption or dependable transactions.
For publishers, the question becomes how original work is credited and paid for when fewer readers visit. For brands, it is whether the agent accurately understands the offer and whose interests guide the recommendation. User preferences, advertising, commissions and platform priorities can point in different directions.
Distribution is already a strategic battleground in providers' own materials. OpenAI and Google describe more persistent personal assistance; Microsoft and Anthropic emphasize work and usage patterns. DeepSeek and Qwen bring Chinese model and tooling ecosystems into the picture, while Mistral offers another work-and-coding route. These are strategic directions, not an independently established ranking. Product access, licenses and capabilities vary.
What prominent voices disagree about
Ethan Mollick's October 2026 essay revises his earlier view of agent organization: he now thinks models can do more of the coordination that he previously expected humans to design. He still leaves open how well this works for long, ordinary organizational tasks. His argument supports experimentation, not a claim that human work has already become dispensable.
Yann LeCun puts more weight on the architecture needed for planning and understanding consequences, arguing for world models and abstraction. Fei-Fei Li stresses a related distinction: a convincing rendering is not necessarily an accurate simulation. These are research judgments, not a settled verdict on what today's systems can achieve.
Yoshua Bengio argues for independent safety evidence, accountability and international coordination as systems gain more power to act. Bruce Schneier draws attention to the humans and organizations configuring and deploying those systems. Responsibility should not disappear behind a story about a machine “going rogue.”
Daron Acemoglu, David Autor and Simon Johnson ask what kind of AI we choose to build: systems that expand human expertise and create new tasks have different implications from systems designed mainly to replace existing work. Abeba Birhane challenges a complementary assumption—that wider adoption automatically means social progress. She calls for evidence of benefits and attention to what communities actually need.
These voices are not disinterested or interchangeable. Mollick is an academic and author; LeCun, Li and Bengio lead or help lead AI organizations; Schneier works with Inrupt. Willison discloses sponsors, applied-AI work and past vendor compensation. The pro-worker paper includes funding disclosures. Birhane's accountability research has a critical policy perspective. Their arguments should be assessed on their merits, with those positions visible. This selection is not a representative survey of world opinion.
Three possible paths: 2029, 2031 and 2036
The following are Atlas scenarios, measured from October 2026. They are ways to test decisions, not predictions with assigned probabilities. Different countries, sectors and customers could experience different combinations.
In user-controlled delegation, useful cross-service tasks spread by 2029. By 2031, agents coordinate recurring work with portable context. By 2036, a personal agent could become a common front door to digital services. This path depends on dependable results, usable permissions and the ability to change providers. Persistent lock-in or heavy rework would weaken it.
In platform gatekeeping, integrated ecosystems deliver the easiest early experience by 2029. By 2031, more discovery and transactions pass through their agents. By 2036, a small set of intermediaries could exert substantial influence over access to customers and creators' income. Easy switching and durable direct relationships would weaken this path.
In uneven automation, short and bounded tasks improve by 2029 while longer chains still need intervention. By 2031, controlled environments move further than open-ended work across the web. By 2036, agents coexist with apps and human services. Repeated, economical success on long tasks across organizations and languages would weaken this scenario.
None of these paths requires a particular AGI arrival date. Monitor completed tasks, intervention rates, total cost, repeated use, provider switching and who controls the customer relationship. A polished demonstration or benchmark improvement alone does not settle those questions.
What brands and companies should do
Now: make the offer dependable. Keep prices, availability, terms, product descriptions and supporting evidence accurate across the channels customers use. Publish material grounded in your own expertise and experience. Google's guidance supports useful original content and clear information; it does not guarantee inclusion in an AI answer.
Now: establish a baseline. Distinguish search traffic, identifiable AI referrals, direct visits and unknown attribution. Track qualified customers and completed purchases as well as visibility. Test one recurring workflow against the current process, measuring acceptable results, errors, review time and total cost. Give it an owner who can stop it and correct mistakes.
Over the next 6–24 months: prepare controlled service access where customers or partners need it. Let an agent check stock or order status before allowing it to change an order. Test local languages and customer journeys. Keep direct human contact available, and plan how junior staff continue to build the judgment needed to supervise the work.
Later: expand delegation when repeated results justify it. Agent-mediated purchasing needs verified identity, bounded authority, transaction records and a route to dispute or reverse mistakes. Consider protocols where actual partners support them. If one platform becomes a major source of customers, measure its effect on margins and preserve alternative routes.
Readable process files can help. A Markdown document can describe the goal, inputs, allowed actions, approval points, checks, stop conditions and responsible owner. But .md is an optional format for instructions, not an enforcement mechanism. The connected systems must apply the permissions. These are editorial recommendations, not an Atlas-tested Playbook.
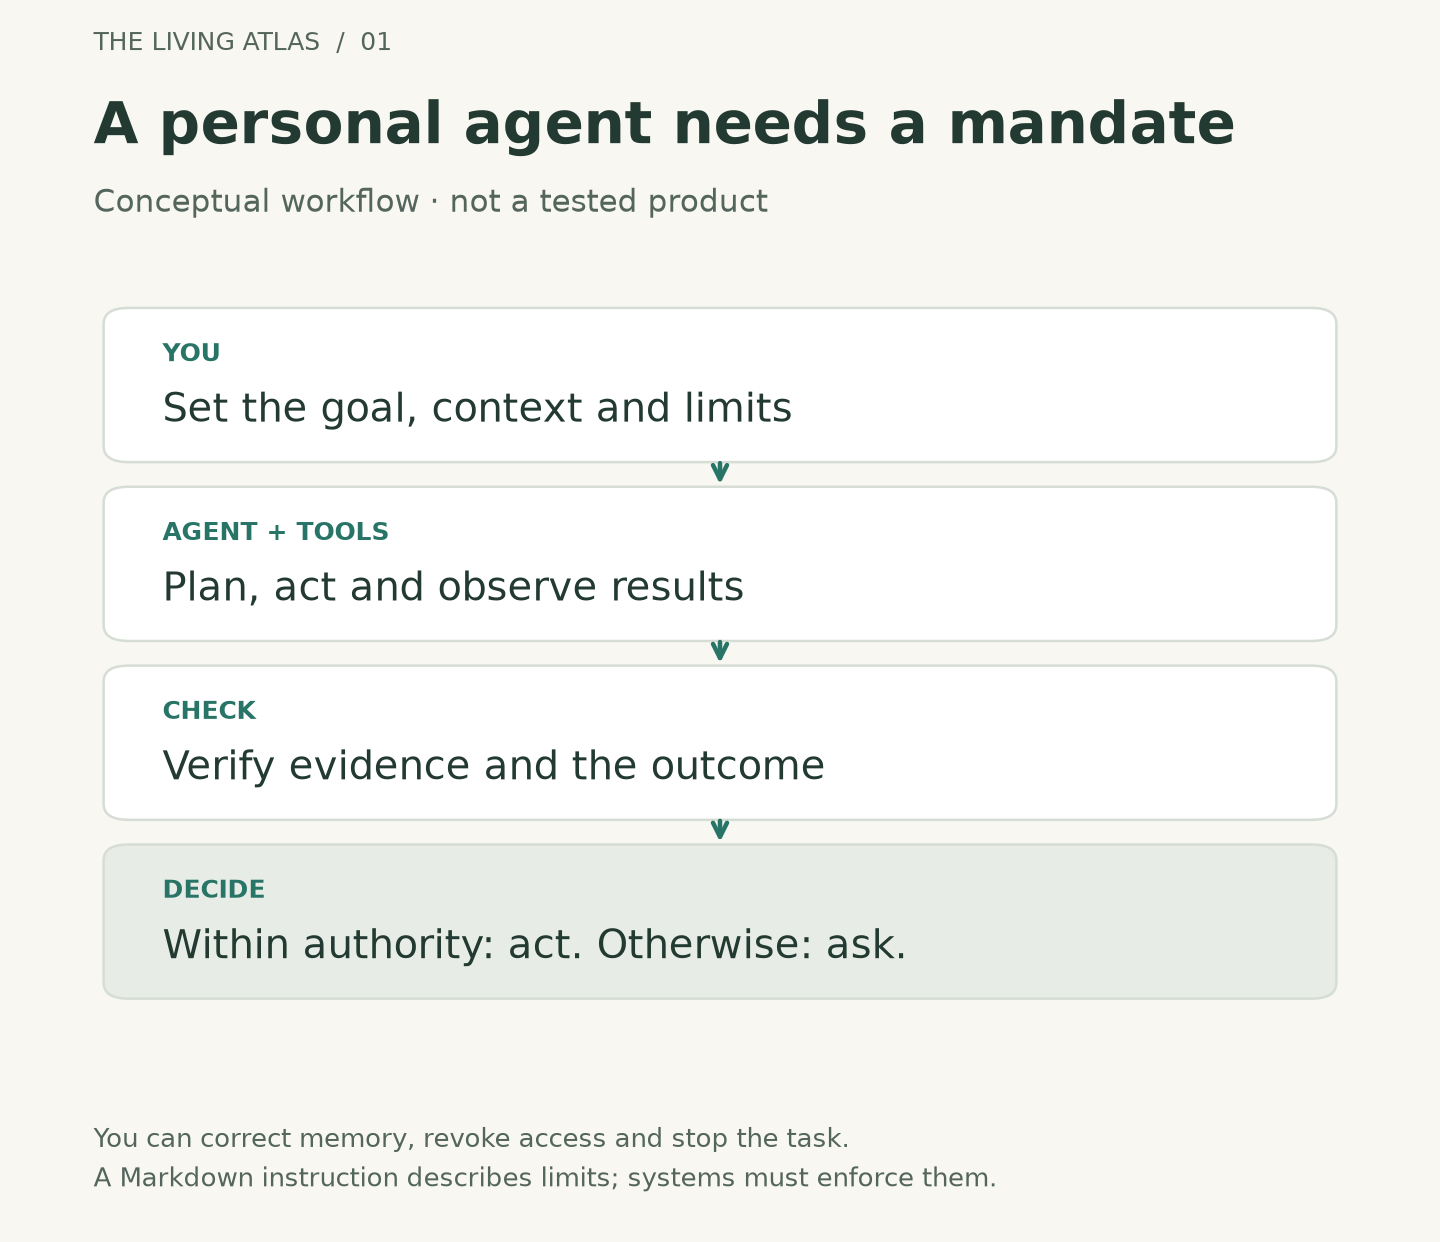
Schematic · not measured data An illustrative agent workflow, not a test of any product. Instructions describe the mandate; connected systems must enforce it.
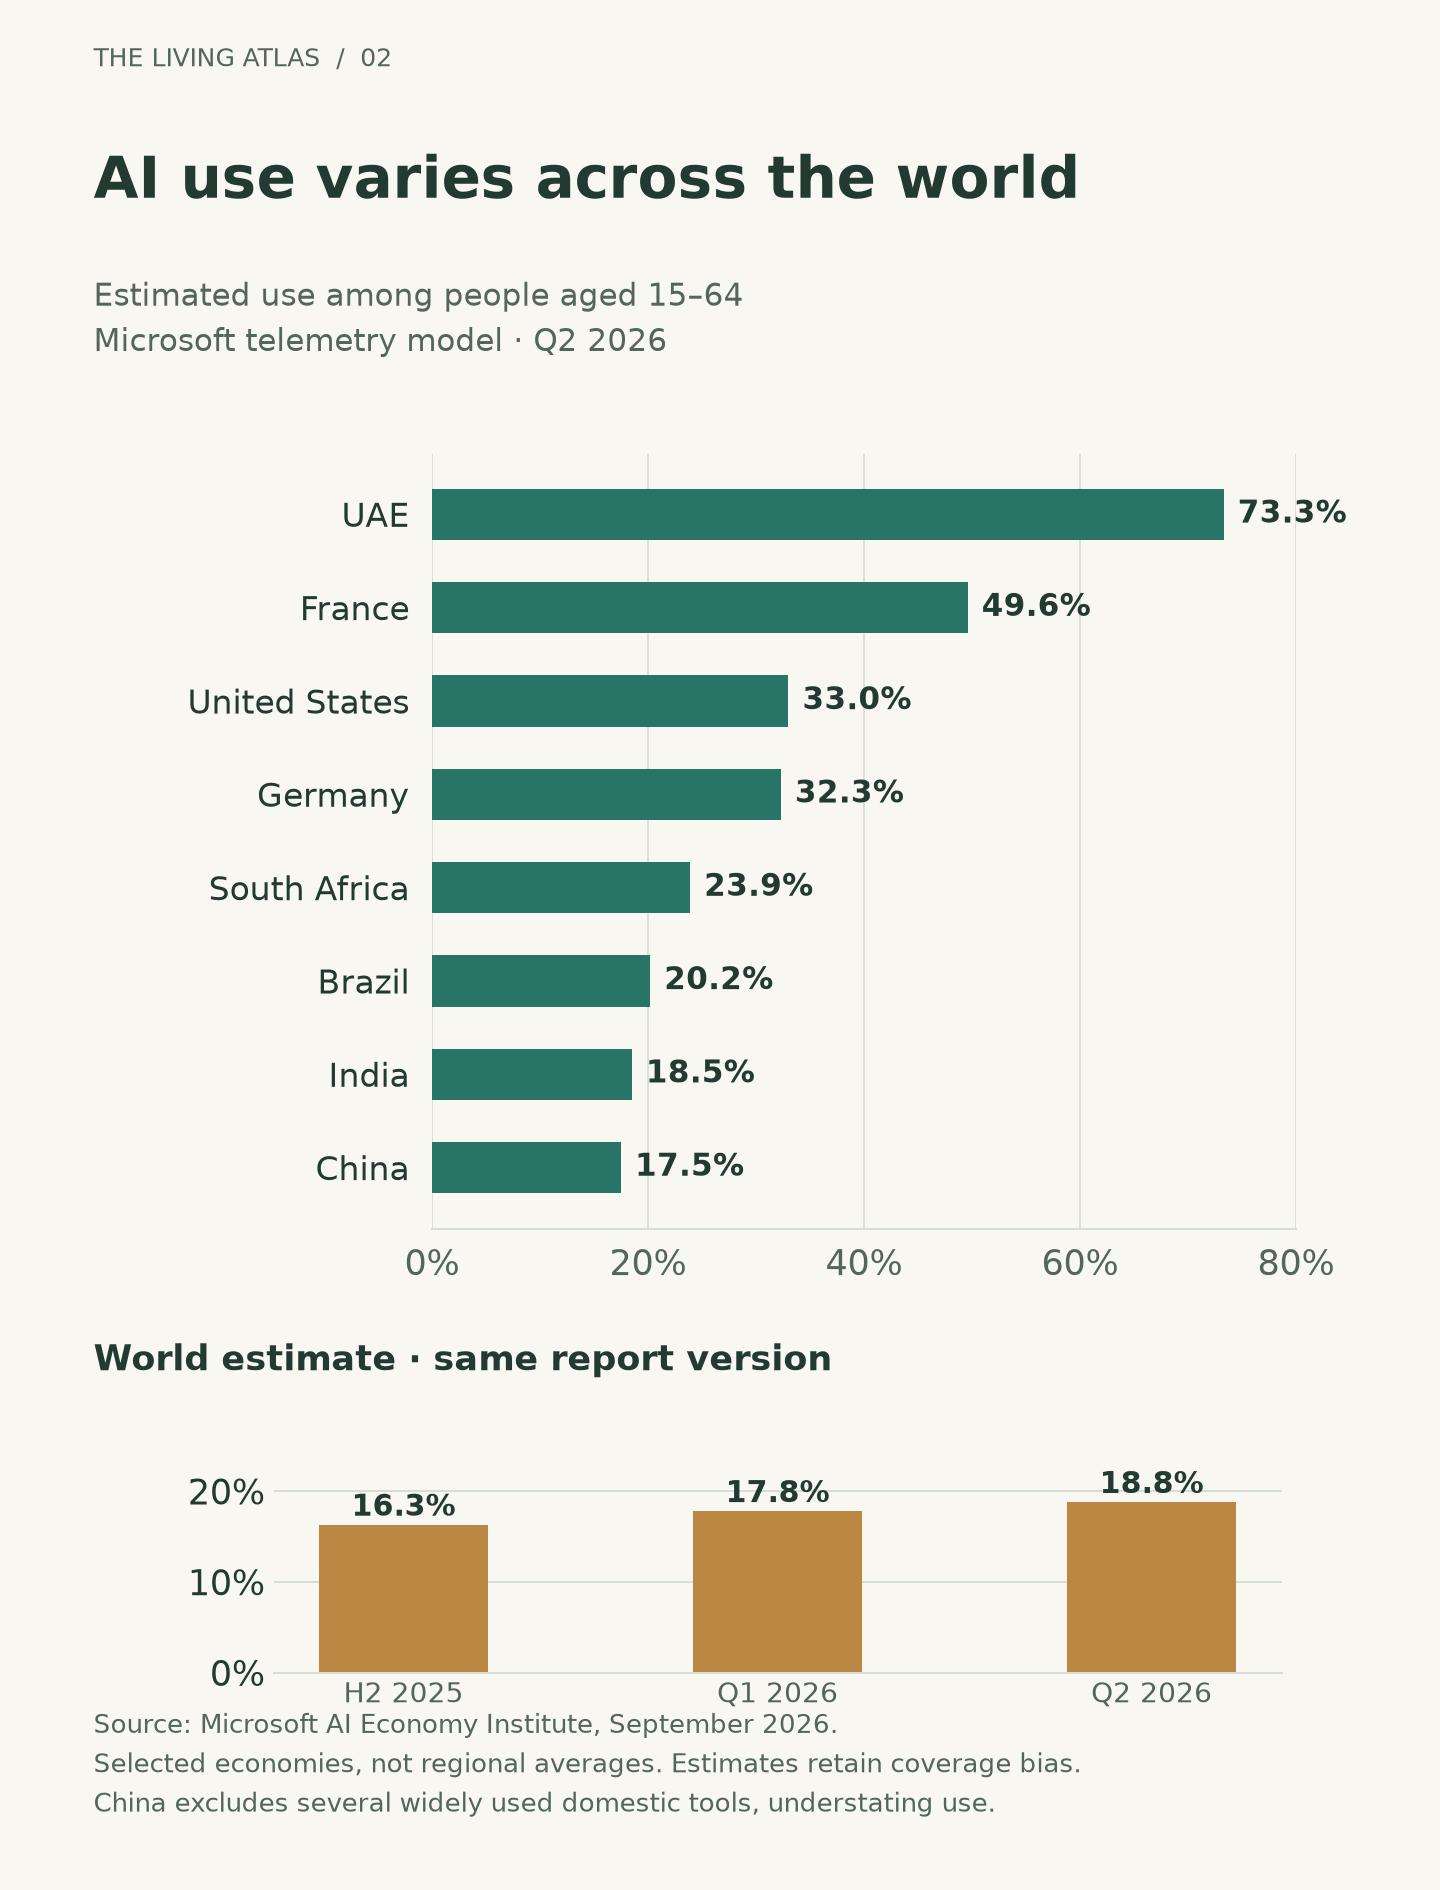
Data chart Microsoft estimates use among people aged 15–64 from adjusted telemetry. Selected economies span several regions; France and Germany are not an EU average. Coverage bias remains. Periods and values come from the same Q2 2026 report; no forecast is shown. Several widely used domestic Chinese tools are missing; Microsoft expects broader coverage to raise the China estimate.
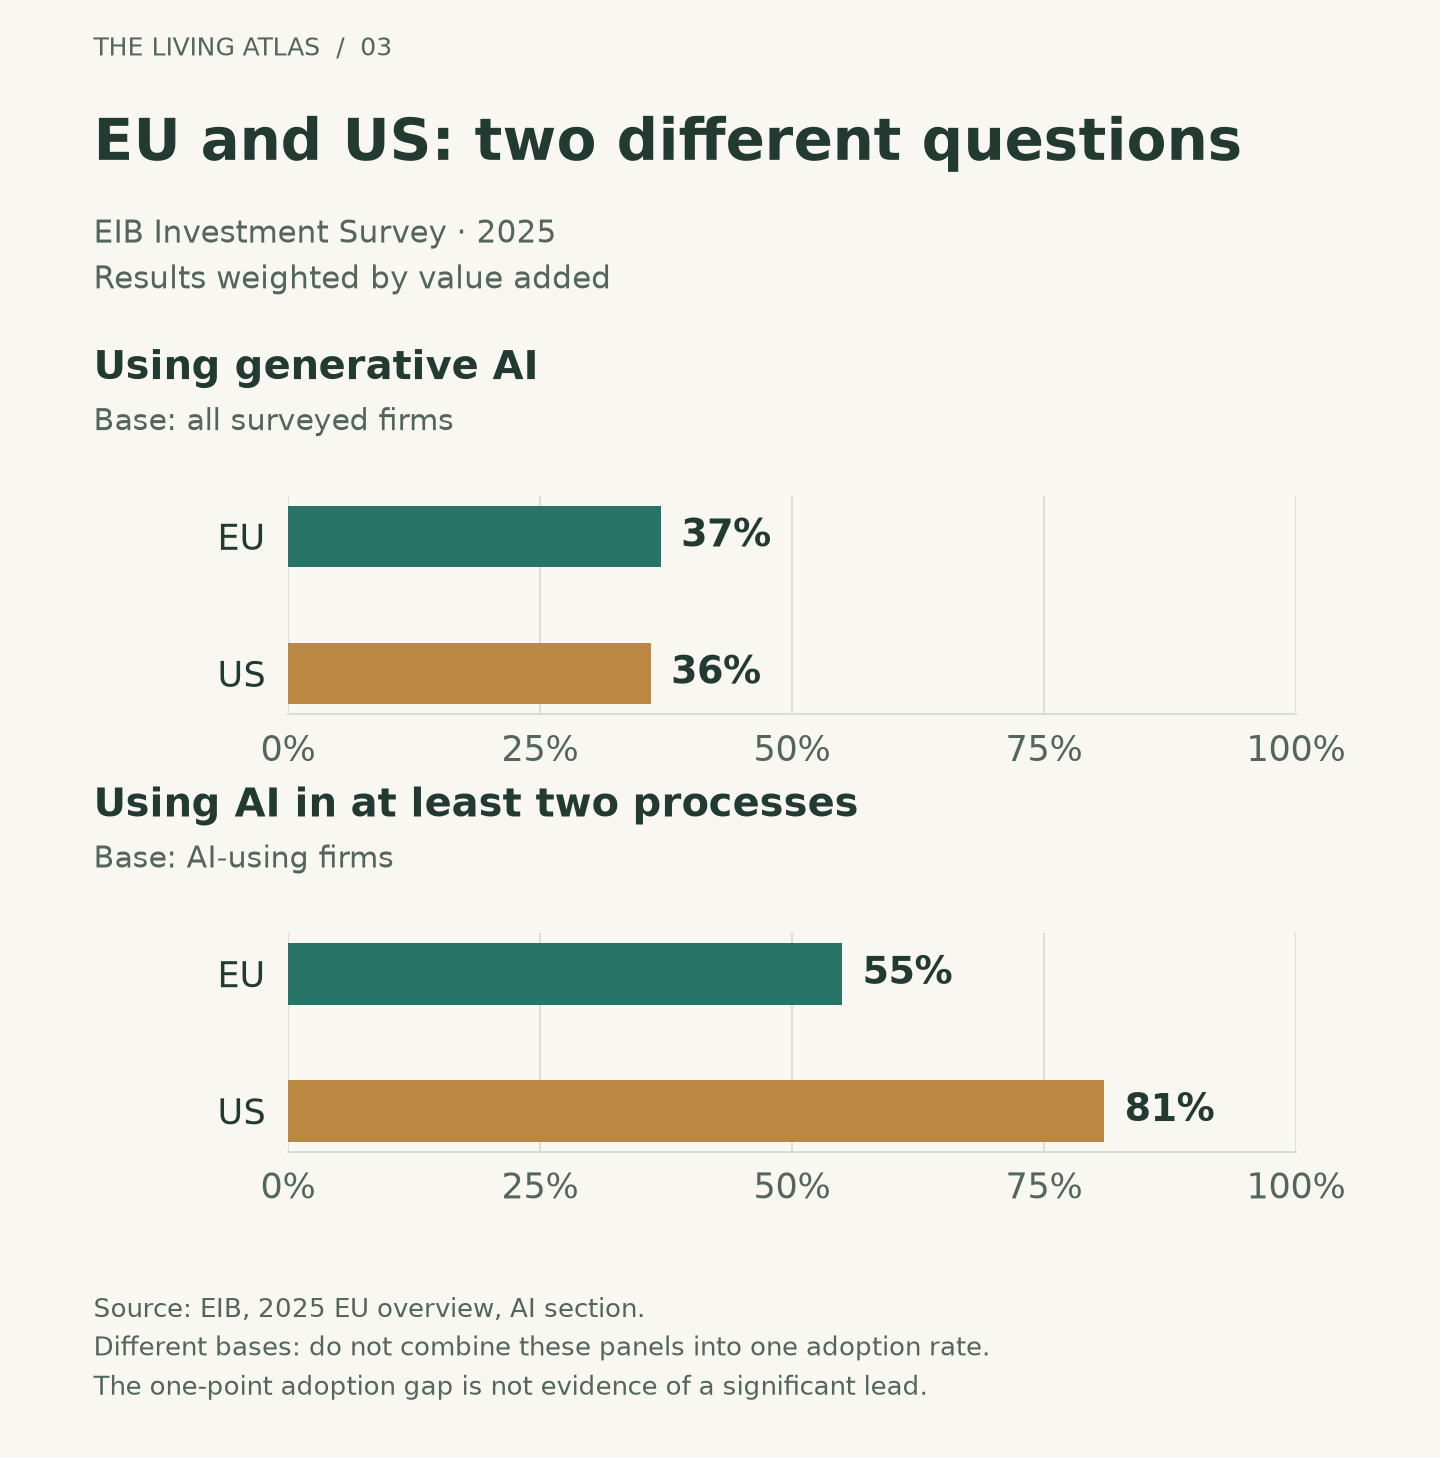
Data chart The same survey compares EU and US firms, using value-added weights. The first panel covers all surveyed firms; the second covers AI users. At least two processes follows the original report. The one-point adoption gap is not presented as statistically significant.
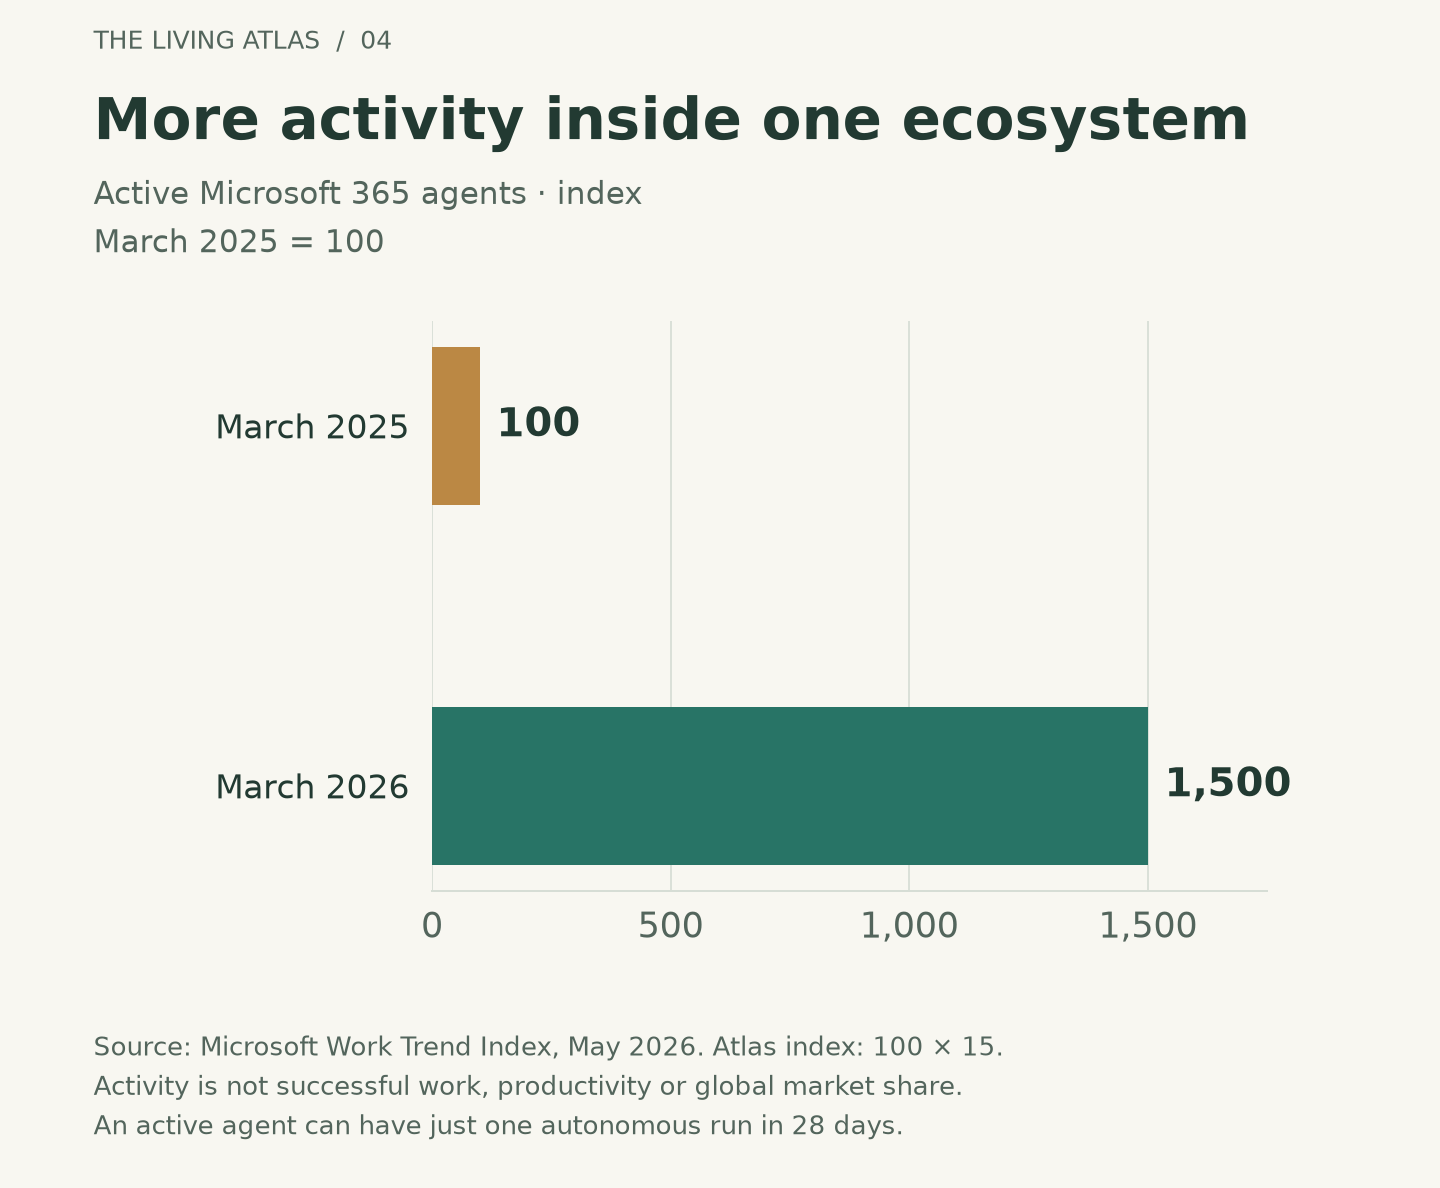
Data chart Atlas converts Microsoft’s reported 15× ratio to an index, 100 × 15 = 1,500. An agent counts as active with at least one day of user-initiated activity or one autonomous run in 28 days. This does not measure successful tasks, people or global adoption.
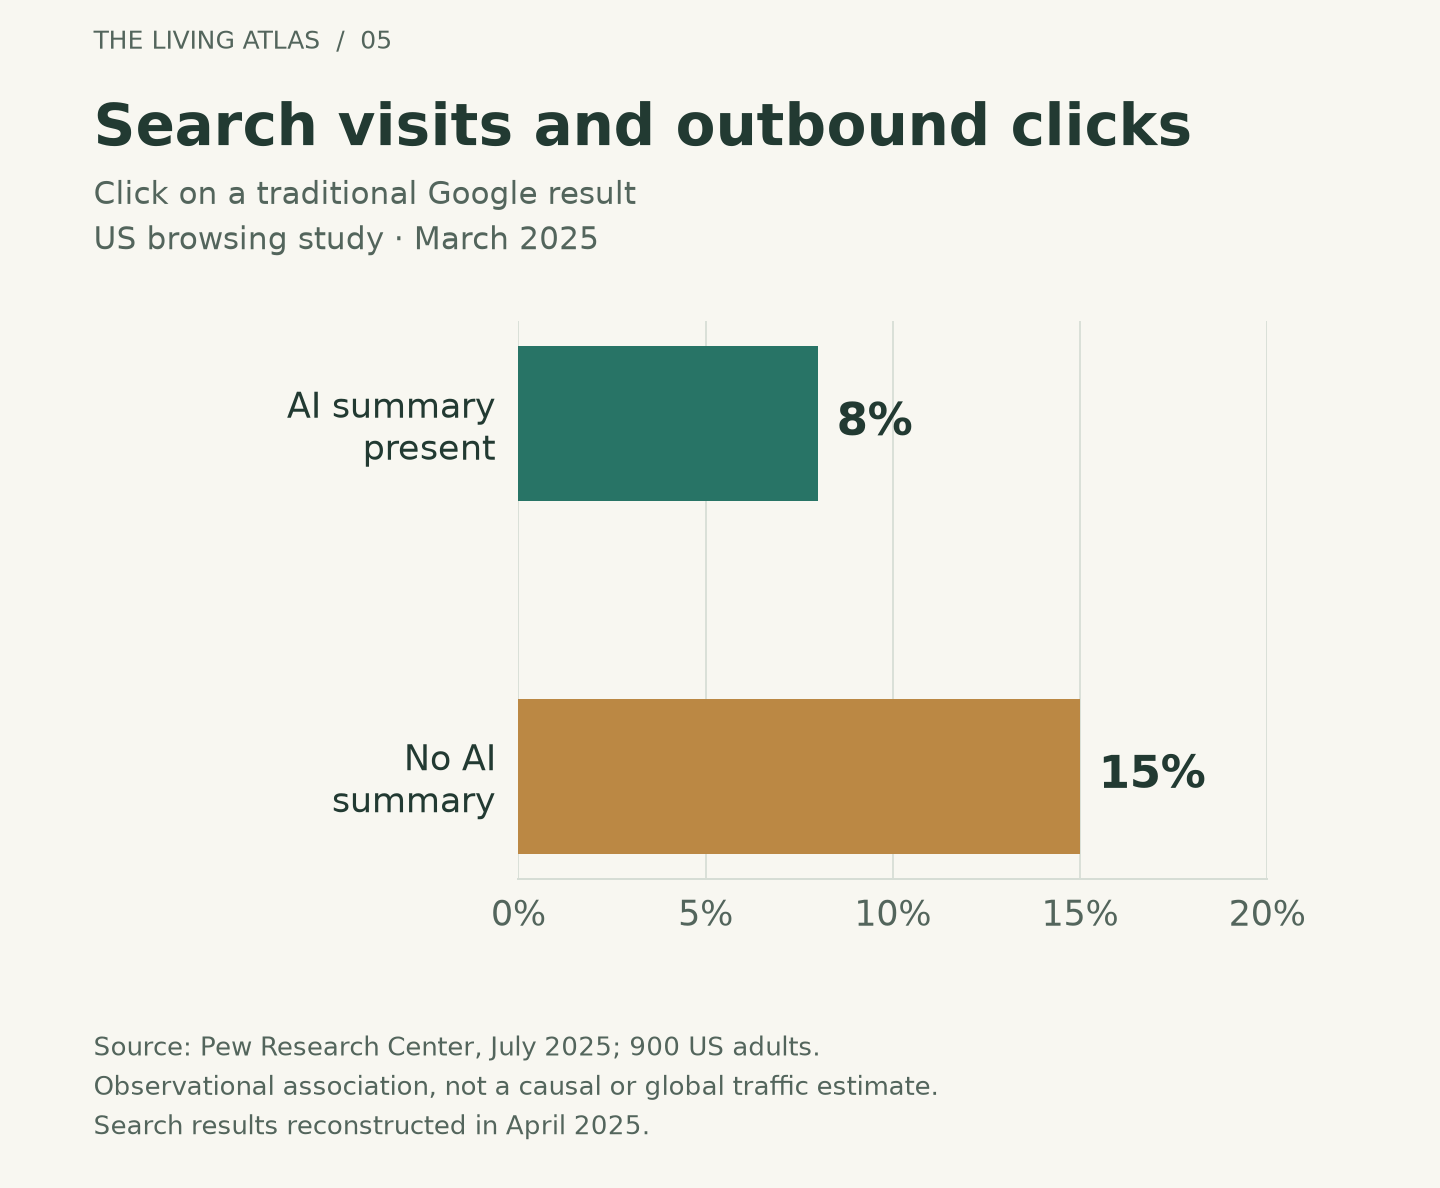
Data chart Observed behavior among 900 US adults. The comparison is not randomized; search questions can differ and results were reconstructed in April. It is not a current worldwide estimate or proof of a causal traffic loss.
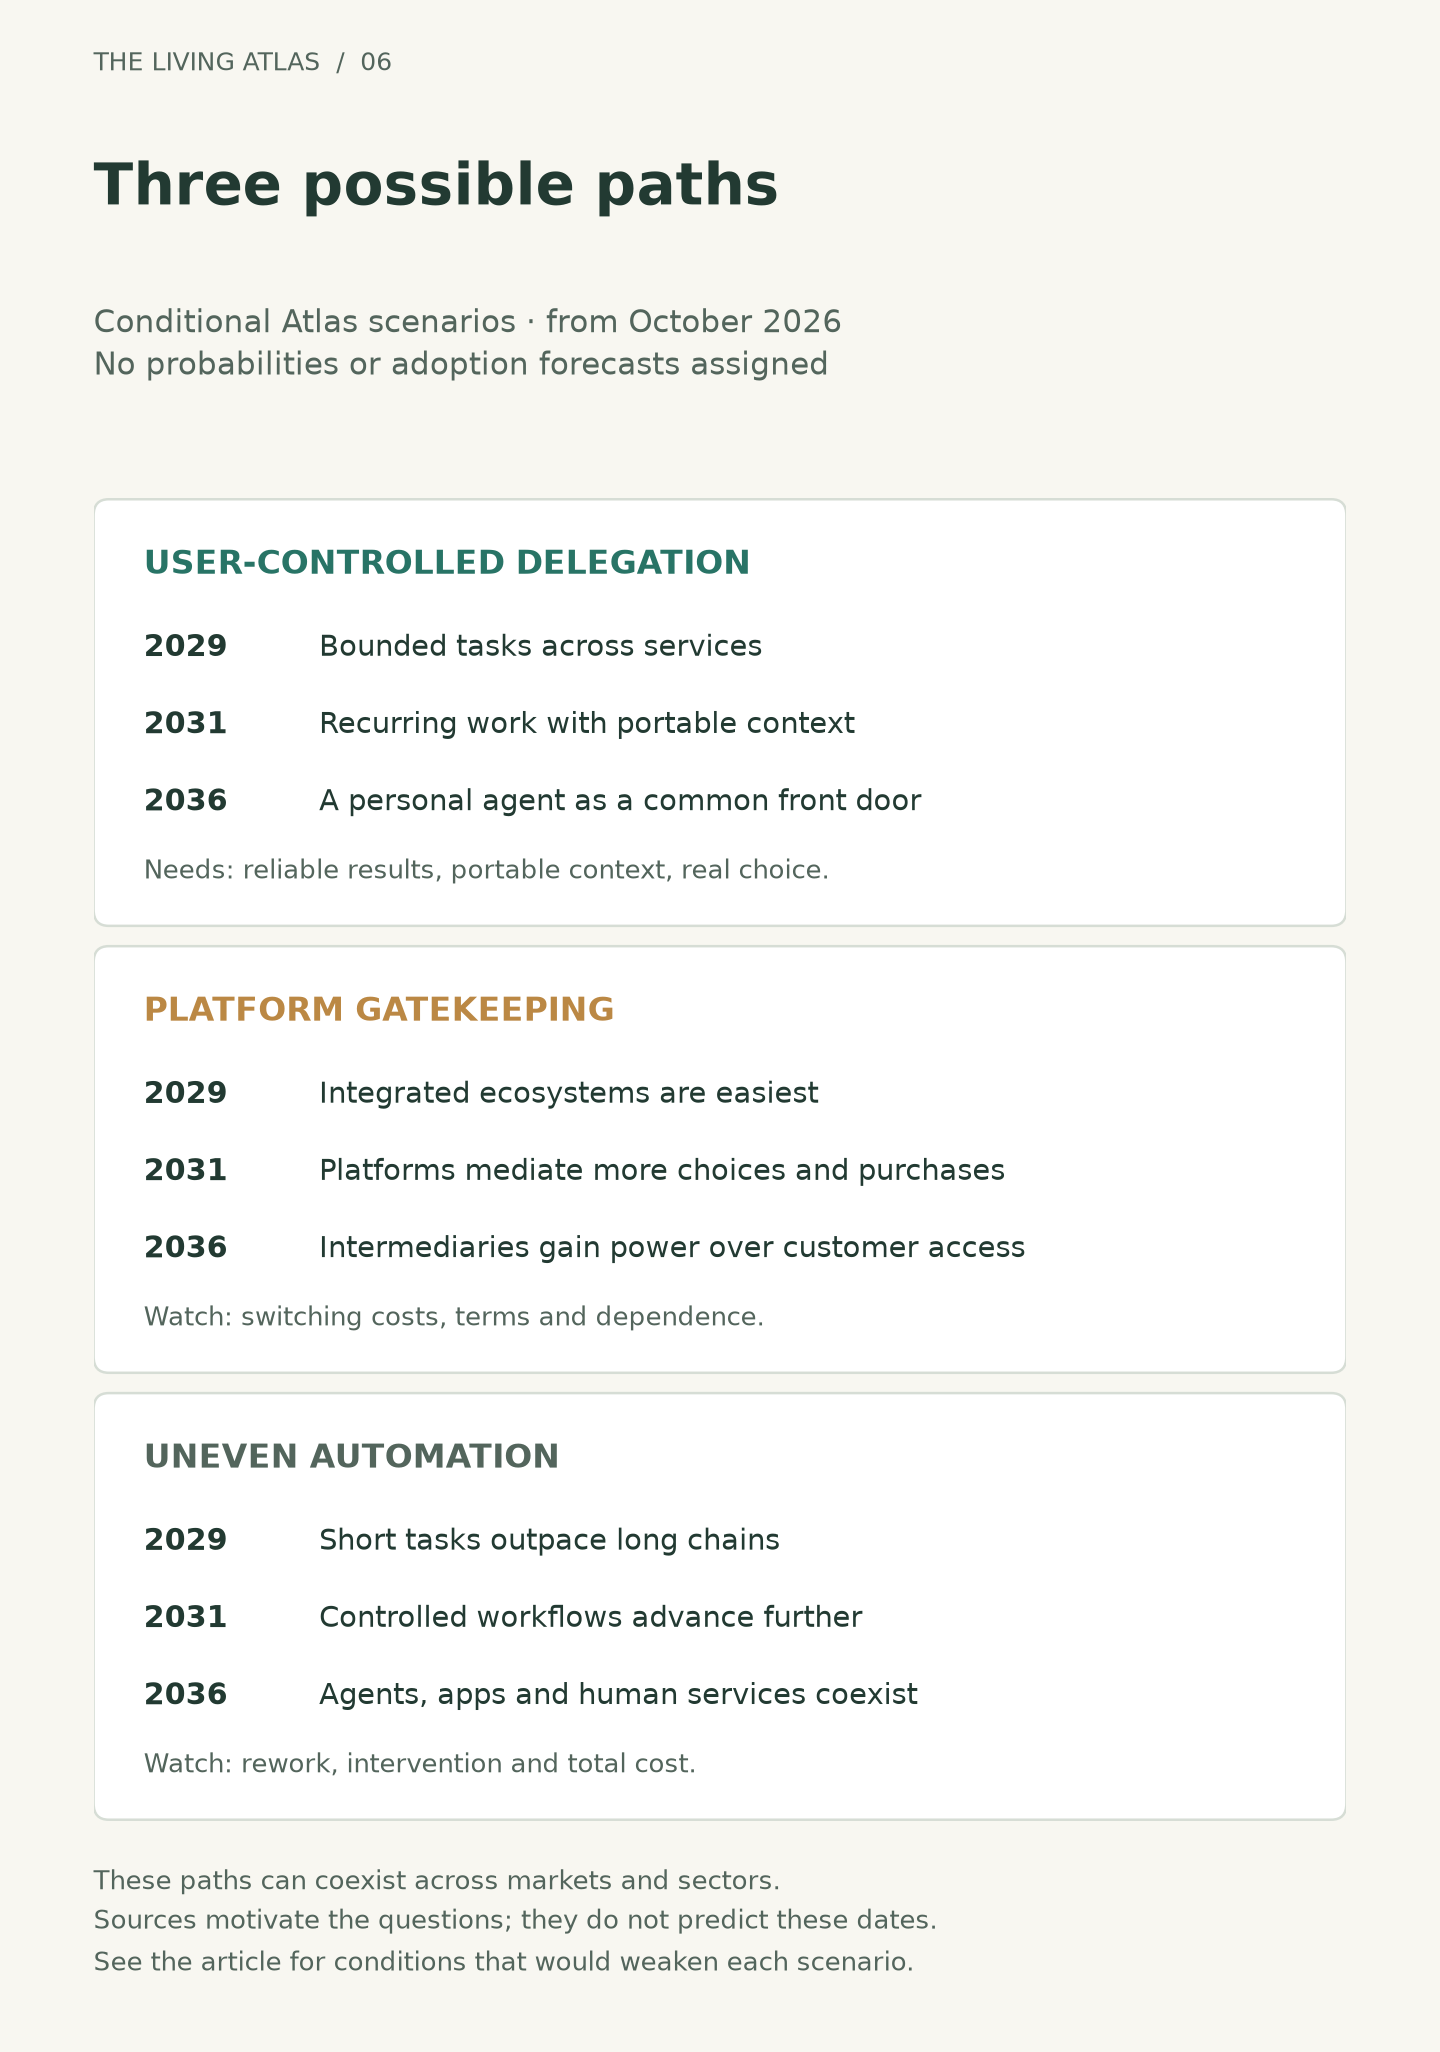
Schematic · not measured data Atlas scenarios from an October 2026 baseline. The paths can coexist; the article states assumptions and evidence that would weaken each one. Sources motivate the questions, not the dates or outcomes.
Sources in this version
- Global AI Diffusion: Q2 2026 ↗Version consulted on 23 October 2026 · PDF pages 2, 5 and 13–16: definitions, global periods and economy tablesPublished September 2026 · recorded in Atlas 23 October 2026
- Measuring AI Diffusion ↗Version consulted on 23 October 2026 · Sections 2 and 4: construction and limitationsPublished 4 November 2025 · recorded in Atlas 23 October 2026
- EIB Investment Survey 2025: EU overview ↗Version consulted on 23 October 2026 · PDF pages 6, 33–34 and 49–50: weighting, AI results and samplePublished 14 October 2025 · recorded in Atlas 23 October 2026
- Agents, human agency, and the opportunity for every organization ↗Version consulted on 23 October 2026 · Redesigning systems and processes; footnote 10; Microsoft 365 Telemetry methodologyPublished 5 May 2026 · recorded in Atlas 23 October 2026
- Google users are less likely to click on links when an AI summary appears in the results ↗Version consulted on 23 October 2026 · Traditional-result clicks and methodologyPublished 22 July 2025 · recorded in Atlas 23 October 2026
- Generative AI at Work ↗Version consulted on 23 October 2026 · Abstract and productivity results in the published versionPublished 4 February 2025 · recorded in Atlas 23 October 2026
- We are Changing our Developer Productivity Experiment Design ↗Version consulted on 23 October 2026 · Discussion of selection, time measurement and interpretationPublished 24 February 2026 · recorded in Atlas 23 October 2026
- What is agentic engineering? ↗Version consulted on 23 October 2026 · Definition of agents, tool loops and verificationPublished 2026 · recorded in Atlas 23 October 2026
- Introducing dots ↗Version consulted on 23 October 2026 · Product description and rollout qualificationsPublished 29 September 2026 · recorded in Atlas 23 October 2026
- The next evolution of the Gemini app ↗Version consulted on 23 October 2026 · Personal assistance and connected-tool plansPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Anthropic Economic Index: Cadences ↗Version consulted on 23 October 2026 · Agentic task patterns and changes to collection methodologyPublished 26 June 2026 · recorded in Atlas 23 October 2026
- DeepSeek V4.1 Flash ↗Version consulted on 23 October 2026 · Efficiency and agent-task emphasisPublished 10 September 2026 · recorded in Atlas 23 October 2026
- Qwen-Agent ↗Version consulted on 23 October 2026 · README: tools, planning, integrations and framework licensePublished 2026 · recorded in Atlas 23 October 2026
- Vibe Agent ↗Version consulted on 23 October 2026 · Context, permissions and reusable work instructionsPublished 28 May 2026 · recorded in Atlas 23 October 2026
- The Dot and the Swarm ↗Version consulted on 23 October 2026 · Revised view of agent organization and closing reservationsPublished 1 October 2026 · recorded in Atlas 23 October 2026
- Learning Abstractions: A Conversation with Yann LeCun ↗Version consulted on 23 October 2026 · Discussion of world models, abstraction and planning; participant biographiesPublished 2026 · recorded in Atlas 23 October 2026
- Why Governing World Models Is AI’s Next Big Policy Challenge ↗Version consulted on 23 October 2026 · Li's distinction between convincing renderings and accurate simulationsPublished 4 August 2026 · recorded in Atlas 23 October 2026
- Professor Yoshua Bengio’s speech to the UN Security Council ↗Version consulted on 23 October 2026 · Independent safety evidence, accountability and international cooperationPublished 23 September 2026 · recorded in Atlas 23 October 2026
- I Want Better Reporting on AI Genie Behavior ↗Version consulted on 23 October 2026 · Responsibility, configuration and descriptions of unwanted agent behaviorPublished 30 September 2026 · recorded in Atlas 23 October 2026
- Building Pro-Worker Artificial Intelligence ↗Version consulted on 23 October 2026 · Abstract, technology categories, expertise and new tasks; acknowledgmentsPublished February 2026 · recorded in Atlas 23 October 2026
- AI for Good ↗Version consulted on 23 October 2026 · Demanding evidence of benefits; community needs and unequal consequencesPublished 10 February 2026 · recorded in Atlas 23 October 2026
- Building an open Agentic Internet ↗Version consulted on 23 October 2026 · Discovery, callable services and transactionsPublished 6 August 2026 · recorded in Atlas 23 October 2026
- Universal Commerce Protocol: specification overview ↗Version consulted on 23 October 2026 · Profiles, capabilities and version negotiationPublished 25 August 2026 · recorded in Atlas 23 October 2026
- AI optimization guide ↗Version consulted on 23 October 2026 · Useful original content, clear information and established search practicesPublished 2026 · recorded in Atlas 23 October 2026