Who decides which ideas deserve an experiment?
Look at what the system can learn from.
Trace one discovery claim from proposal to check. Identify who designed the test, what could fail, and whether anyone has reproduced the finding.
This is a suggested direction based on archival research, not a promise of a future discovery. No automatic monitoring has been started.
Reported finding: Predicted candidates were made and measured
Reported findingThe robotic chemistry study combined theoretical calculations, neural networks and physical experiments to identify a catalyst.
Scope and conditions: A laboratory demonstration on Earth within a defined chemistry setup; neither a Mars deployment nor an independently replicated general discovery system.
Independent evidence · origin, not a quality ratingSource passage · 2023Full-text link is the author preprint. The journal abstract corroborates the combined computational and experimental method.
Published abstract and Figures 1–4; author preprint pp. 6–9 and 16, models and experimental workflow About the source and its version
What changed, and why.
This history comes from saved content versions. A new revision can be an editorial change; it does not by itself mean that the underlying facts changed.
Assessment changed · revision 2
Refines headings, transitions and prose while preserving research claims, examples and interactive figures.
Compare revision 1 with 2
Section order
A new result can start with old knowledge. → A mathematical answer that could be checked. → In chemistry, the answer has to survive a measurement. → Two days of hypotheses are not years of experiments. → The proposal and the judge do different jobs. → Physics narrows the possibilities. Assumptions still matter. → Physics in the training objective is no guarantee. → The scarce skill may be deciding what deserves a test.
A new result can start with old knowledge. → In mathematics, code can check the answer. → In chemistry, a prediction has to meet a measurement. → Two days of hypotheses are not years of experiments. → The proposal and the judge do different jobs. → Physics narrows the possibilities. Assumptions still matter. → Adding physics to training does not guarantee success. → The scarce skill may be deciding what deserves a test.
Section: A new result can start with old knowledge.
A model’s training material is a starting point. It can learn patterns for composing code or proposing structures, then use them to generate candidates that no one supplied as finished answers. Most candidates may be useless. A search process can still improve if it has a reliable way to recognise a better one. To understand how that happens, look at the whole system: who defines the problem, what the model can propose, what tests the proposal, and how the result changes the next attempt. A fluent answer alone tells us little about those steps. Novelty also depends on who already knew. A result can be new to the model, new to one research team, or new to the scientific record. Those are different achievements, as the following cases show.
A model’s training material gives it a starting point. It can learn patterns for writing code or proposing structures, then generate candidates that no one supplied as finished answers. Most may be useless. But with a reliable way to recognise a better candidate, the search can improve. To see how, follow the whole system: who defines the problem, what the model can propose, what tests each proposal and how the result guides the next attempt. A fluent answer alone tells us little about those steps. There is also a question of who knew first. A result can be new to the model, new to one research team or new to the scientific record. The following cases show why that distinction matters.
Section: In mathematics, code can check the answer.
In 2023, Bernardino Romera-Paredes and colleagues at Google DeepMind and universities reported FunSearch. A language model proposed small programs; an evaluator ran them, discarded invalid outputs and scored useful ones. Better programs informed later prompts. For the cap-set problem—finding large sets of points that avoid a specified three-point pattern—it produced a construction with 512 points in eight dimensions, exceeding the then-known record. It did not solve the whole problem or prove that 512 was the largest possible. The human contribution included the problem, evaluator and program structure. The model supplied variations. Search and checking turned some of those variations into a new mathematical result.
In 2023, Bernardino Romera-Paredes and colleagues at Google DeepMind and universities reported FunSearch. A language model proposed small programs; an evaluator ran them, discarded invalid outputs and scored useful ones. Better programs informed later prompts. For the cap-set problem—finding large sets of points that avoid a specified three-point pattern—it produced a construction with 512 points in eight dimensions, exceeding the then-known record. It did not solve the whole problem or prove that 512 was the largest possible. People defined the problem, built the evaluator and set the program structure. The model supplied variations. Search and checking turned some of those variations into a new mathematical result.
Section: In chemistry, a prediction has to meet a measurement.
A team led by the University of Science and Technology of China (USTC), including Jun Jiang, Weiwei Shang and Yi Luo, reported a robotic chemist in 2023. It used meteorite material to develop catalysts for releasing oxygen from water. This was a laboratory demonstration on Earth. The system combined theoretical calculations with experimental data to select promising candidates, then made and tested the proposed catalyst. The result was a material whose performance had been measured in a setup designed by researchers. The models and robot did different jobs. A calculation can make a candidate worth trying. The measurement supplies information the prediction itself cannot provide: how that material behaves under those test conditions.
A team led by the University of Science and Technology of China (USTC), including Jun Jiang, Weiwei Shang and Yi Luo, reported a robotic chemist in 2023. It used meteorite material to develop catalysts for releasing oxygen from water. This was a laboratory demonstration on Earth. The system combined theoretical calculations with experimental data to select promising candidates, then made and tested the proposed catalyst. Researchers designed the setup in which its performance was measured. The models predicted; the robot made and tested the material. A calculation can make a candidate worth trying. A measurement adds something the prediction cannot supply on its own: how the material actually behaves under those test conditions.
Section: Two days of hypotheses are not years of experiments.
Google’s Co-Scientist offers a different example. Its 2026 Nature paper reports that the system recovered, in two days, a mechanism of bacterial gene transfer already found by an experimental team but not yet published. Matching a withheld result is valuable evidence of hypothesis-generation ability. Establishing that result had still required laboratory work. The same paper describes other suggestions followed by laboratory validation. It also acknowledges preliminary evidence, limits to factual accuracy and gaps in access to scientific literature. This is a collaboration between Google and academic researchers, not an independent assessment of Google’s system. The distinction is useful whenever a headline compresses a long research programme into the time taken to generate an idea. Ask what the clock includes.
Google’s Co-Scientist offers a different kind of result. Its 2026 Nature paper reports that, in two days, the system recovered a mechanism of bacterial gene transfer that an experimental team had already found but not yet published. Matching that withheld finding is valuable evidence of an ability to generate hypotheses. Establishing it had still required laboratory work. The same paper describes other suggestions followed by laboratory validation. It also acknowledges preliminary evidence, limits to factual accuracy and gaps in access to scientific literature. This is a collaboration between Google and academic researchers, not an independent assessment of Google’s system. When a headline compresses a long research programme into the time taken to generate an idea, ask what the clock includes.
Section: The proposal and the judge do different jobs.
Notice what sits outside the model in each case. A coded rule can reject an invalid construction. An instrument can reveal a failed prediction. A withheld result can test whether the system recovers something it was not explicitly told. None of those checks becomes stronger merely because several language models agree. The feedback is therefore a central design choice: what would make the system change its mind? If the only response is that another model finds the answer convincing, the process may refine plausibility without acquiring new evidence.
Notice what sits outside the model in each case. A coded rule can reject an invalid construction. An instrument can reveal a failed prediction. A withheld result can test whether the system recovers something it was not explicitly told. None of those checks becomes stronger merely because several language models agree. That makes feedback a central design choice. What would make the system change its mind? If another model simply finds the answer convincing, the process may make an idea sound more plausible without adding new evidence.
Section: Physics narrows the possibilities. Assumptions still matter.
Physics-informed neural networks, or PINNs, offer another way to guide a model. In the classical approach described by Maziar Raissi, Paris Perdikaris and George Karniadakis, training penalises both disagreement with observations and violations of specified physical equations. The model is asked to fit the data and respect a chosen description of the world. This can help where observations are sparse, or help estimate unknown parameters within an assumed equation. But solving a known equation, inferring a parameter and discovering a new physical law are different claims. The illustration below shows how assumptions shape a prediction; it does not train a neural network.
Physics-informed neural networks, or PINNs, offer another way to guide a model. In the classical approach described by Maziar Raissi, Paris Perdikaris and George Karniadakis, training penalises two kinds of mismatch: disagreement with observations and violations of specified physical equations. The model must try to fit the data while respecting a chosen description of the world. This can help where observations are sparse, or help estimate unknown parameters within an assumed equation. But solving a known equation, inferring a parameter and discovering a new physical law are different claims. The illustration below shows how assumptions shape a prediction; it does not train a neural network.
Section: Adding physics to training does not guarantee success.
Aditi Krishnapriyan and colleagues demonstrated another limit in a 2021 study: penalties for violating physical equations could make some training problems difficult to optimise. A network capable of expressing a solution might still fail to learn it. They also explored ways to improve training. The result concerns specific methods and problems, not every physics-informed model. That leaves two distinct checks. Does the model solve the problem it was given? And was that the right problem for the physical situation? Better optimisation can address the first while leaving the second untouched.
Aditi Krishnapriyan and colleagues showed another limit in a 2021 study. Penalties for violating physical equations could make some training problems difficult to optimise: a network capable of expressing a solution might still fail to learn it. The researchers also explored ways to improve training. Their result concerns specific methods and problems, not every physics-informed model. That leaves two distinct checks. Does the model solve the problem it was given? And was that the right problem for the physical situation? Better optimisation can address the first while leaving the second untouched.
Section: The scarce skill may be deciding what deserves a test.
Across these cases, people still determined what was worth asking, what counted as progress and what could be checked. A search can be highly effective within those choices while overlooking an important question outside them. Atlas’s interpretation is that cheaper proposals can shift the bottleneck towards evaluation. In some mathematical problems, checks can be automated. In physical research, suitable instruments, materials and experiments may remain expensive or slow. Access to a model does not by itself provide access to a laboratory. For anyone using AI in research or analysis, a useful habit is to pair each proposal with a check that could distinguish it from a plausible rival. What observation would tell them apart? An answer that tells you what to test next can be more valuable than one that merely sounds complete.
In each case, people decided what was worth asking, what counted as progress and what could be checked. A search can work extremely well within those choices and still miss an important question outside them. Atlas’s interpretation is that, as proposals become cheaper to generate, evaluating them may become the bottleneck. Some mathematical checks can be automated. In physical research, suitable instruments, materials and experiments may remain expensive or slow. Access to a model does not by itself provide access to a laboratory. For anyone using AI in research or analysis, a useful habit is to pair each proposal with a check that could distinguish it from a plausible rival. What observation would tell them apart? An answer that tells you what to test next can be more valuable than one that merely sounds complete.
Sources used before
- Mathematical discoveries from program search with large language models ↗Published article; linked access version identified below · FunSearch: Evaluation; Cap sets; Discussion; Figure 4Published 14 December 2023 · recorded in Atlas 23 October 2026
- Automated synthesis of oxygen-producing catalysts from Martian meteorites by a robotic AI chemist ↗Published article; linked access version identified below · Published abstract and Figures 1–4; author preprint pp. 6–9 and 16, models and experimental workflowPublished 13 November 2023 · recorded in Atlas 23 October 2026
- Accelerating scientific discovery with Co-Scientist ↗Published article; linked access version identified below · Recapitulating a breakthrough in AMR; Discussion; Methods: OverviewPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations ↗Published article; linked access version identified below · Author method page: Continuous Time Models, MSE = MSE_u + MSE_f; Data-driven DiscoveryPublished 1 February 2019 · recorded in Atlas 23 October 2026
- Characterizing possible failure modes in physics-informed neural networks ↗Published article; linked access version identified below · Sections 2–4: failure modes, loss landscapes, curriculum and sequence learningPublished 2021 · recorded in Atlas 23 October 2026
Sources used after
- Mathematical discoveries from program search with large language models ↗Published article; linked access version identified below · FunSearch: Evaluation; Cap sets; Discussion; Figure 4Published 14 December 2023 · recorded in Atlas 23 October 2026
- Automated synthesis of oxygen-producing catalysts from Martian meteorites by a robotic AI chemist ↗Published article; linked access version identified below · Published abstract and Figures 1–4; author preprint pp. 6–9 and 16, models and experimental workflowPublished 13 November 2023 · recorded in Atlas 23 October 2026
- Accelerating scientific discovery with Co-Scientist ↗Published article; linked access version identified below · Recapitulating a breakthrough in AMR; Discussion; Methods: OverviewPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations ↗Published article; linked access version identified below · Author method page: Continuous Time Models, MSE = MSE_u + MSE_f; Data-driven DiscoveryPublished 1 February 2019 · recorded in Atlas 23 October 2026
- Characterizing possible failure modes in physics-informed neural networks ↗Published article; linked access version identified below · Sections 2–4: failure modes, loss landscapes, curriculum and sequence learningPublished 2021 · recorded in Atlas 23 October 2026
Available version records (2)
Revision 2 · Assessment changed · reviewed
Refines headings, transitions and prose while preserving research claims, examples and interactive figures.
Answer in this version
Trace one discovery claim from proposal to check. Identify who designed the test, what could fail, and whether anyone has reproduced the finding.
What remained unresolved
Prospective comparisons with realistic baselines, failed attempts, total experimental costs and independent replication.
Takeaway and scope
Yes—AI can help discover new knowledge. The strongest cases connect generated ideas to checks outside the model: executable rules, experiments and measurements. Novelty and correctness both need evidence.
Concrete research cases, with different kinds of evidence. No claim that AI can autonomously solve science as a whole.
A generated construction exceeded the known record
FunSearch reported a new 512-point cap set in eight dimensions.
A 2023 result for a defined mathematical problem, not proof of general scientific autonomy.
Predicted candidates were made and measured
The robotic chemistry study combined theoretical calculations, neural networks and physical experiments to identify a catalyst.
A laboratory demonstration on Earth within a defined chemistry setup; neither a Mars deployment nor an independently replicated general discovery system.
Rediscovery and a new discovery are different claims
Co-Scientist recovered an unpublished bacterial gene-transfer finding in a reported two days.
This timing describes hypothesis generation, not the completion of the underlying laboratory work.
Physical laws can shape the training objective
The classical PINN setup combines fitting observations with penalising disagreement with specified differential equations.
A soft penalty is not exact enforcement; known equations and boundary conditions still need to match the problem.
Physics-informed training can still fail
The study traced failures to difficult optimisation, despite sufficient network capacity.
These are specific 2021 methods and benchmark problems, not evidence that all subsequent physics-informed models fail.
Explanation in this version
A new result can start with old knowledge.
A model’s training material gives it a starting point. It can learn patterns for writing code or proposing structures, then generate candidates that no one supplied as finished answers. Most may be useless. But with a reliable way to recognise a better candidate, the search can improve.
To see how, follow the whole system: who defines the problem, what the model can propose, what tests each proposal and how the result guides the next attempt. A fluent answer alone tells us little about those steps.
There is also a question of who knew first. A result can be new to the model, new to one research team or new to the scientific record. The following cases show why that distinction matters.
In mathematics, code can check the answer.
In 2023, Bernardino Romera-Paredes and colleagues at Google DeepMind and universities reported FunSearch. A language model proposed small programs; an evaluator ran them, discarded invalid outputs and scored useful ones. Better programs informed later prompts.
For the cap-set problem—finding large sets of points that avoid a specified three-point pattern—it produced a construction with 512 points in eight dimensions, exceeding the then-known record. It did not solve the whole problem or prove that 512 was the largest possible.
People defined the problem, built the evaluator and set the program structure. The model supplied variations. Search and checking turned some of those variations into a new mathematical result.
In chemistry, a prediction has to meet a measurement.
A team led by the University of Science and Technology of China (USTC), including Jun Jiang, Weiwei Shang and Yi Luo, reported a robotic chemist in 2023. It used meteorite material to develop catalysts for releasing oxygen from water. This was a laboratory demonstration on Earth.
The system combined theoretical calculations with experimental data to select promising candidates, then made and tested the proposed catalyst. Researchers designed the setup in which its performance was measured. The models predicted; the robot made and tested the material.
A calculation can make a candidate worth trying. A measurement adds something the prediction cannot supply on its own: how the material actually behaves under those test conditions.
Two days of hypotheses are not years of experiments.
Google’s Co-Scientist offers a different kind of result. Its 2026 Nature paper reports that, in two days, the system recovered a mechanism of bacterial gene transfer that an experimental team had already found but not yet published. Matching that withheld finding is valuable evidence of an ability to generate hypotheses. Establishing it had still required laboratory work.
The same paper describes other suggestions followed by laboratory validation. It also acknowledges preliminary evidence, limits to factual accuracy and gaps in access to scientific literature. This is a collaboration between Google and academic researchers, not an independent assessment of Google’s system.
When a headline compresses a long research programme into the time taken to generate an idea, ask what the clock includes.
The proposal and the judge do different jobs.
Notice what sits outside the model in each case. A coded rule can reject an invalid construction. An instrument can reveal a failed prediction. A withheld result can test whether the system recovers something it was not explicitly told. None of those checks becomes stronger merely because several language models agree.
That makes feedback a central design choice. What would make the system change its mind? If another model simply finds the answer convincing, the process may make an idea sound more plausible without adding new evidence.
Research pathways · Atlas synthesis The test changes what a result can establish.
FunSearch · provider and academic research · 2023
- Researchers
Frame
Define the problem and checker.
- Language model
Propose
Generate a candidate program.
- Evaluator
Check
Run it; reject invalid outputs.
- Search system
Keep
Retain useful constructions.
Checked programs help shape the next proposals.
What this establishedA construction beyond the then-known record.
A better construction need not be the best possible one.
These are different studies, not a head-to-head performance comparison. The paths simplify the reported methods.
Read all research pathways
Mathematics
FunSearch · provider and academic research · 2023
- Frame · Researchers. Define the problem and checker.
- Propose · Language model. Generate a candidate program.
- Check · Evaluator. Run it; reject invalid outputs.
- Keep · Search system. Retain useful constructions.
Checked programs help shape the next proposals.
What this establishedA construction beyond the then-known record.
A better construction need not be the best possible one.
Study & evidence ↗Chemistry
USTC-led academic research · China · 2023
- Define · Researchers. Choose materials and test conditions.
- Predict · Models. Select promising compositions.
- Make · Laboratory robot. Prepare the material.
- Measure · Instruments. Test catalytic performance.
Experimental data inform the predictive model.
What this establishedA candidate supported by laboratory measurements.
Performance outside the tested conditions remains a separate question.
Study & evidence ↗Rediscovery
Co-Scientist · provider and academic research · 2026
- Withhold · Researchers. Keep the result unpublished.
- Propose · AI system. Generate explanations.
- Compare · Researchers. Check against the experimental finding.
- Interpret · Readers. Separate rediscovery from first discovery.
What this establishedA hypothesis matching an unpublished finding.
This does not replace the experiments that established it.
Study & evidence ↗Physics narrows the possibilities. Assumptions still matter.
Physics-informed neural networks, or PINNs, offer another way to guide a model. In the classical approach described by Maziar Raissi, Paris Perdikaris and George Karniadakis, training penalises two kinds of mismatch: disagreement with observations and violations of specified physical equations. The model must try to fit the data while respecting a chosen description of the world.
This can help where observations are sparse, or help estimate unknown parameters within an assumed equation. But solving a known equation, inferring a parameter and discovering a new physical law are different claims. The illustration below shows how assumptions shape a prediction; it does not train a neural network.
Atlas illustration · calculated, not measured Two readings do not determine the future.
Imagine an object at 80°C, then 40°C ten minutes later. Both curves below pass through those readings. Look at what happens after them.
- Straight-line fit
- Cooling in a steady 20°C room
- Given readings
Both fit. Their predictions disagree.
At 20 minutes, the straight line reaches 0°C and the cooling curve reaches about 27°C. Fitting the supplied readings alone does not tell us which assumption is appropriate.
A calculated teaching example, not measured data, a trained PINN or evidence of model accuracy.
Read all cases, values & method
Newton’s cooling model: T(t) = 20 + 60 exp(−kt), with k = ln(3)/10 per minute. The line is T(t) = 80 − 4t. In the changed-room case, from t = 10: T(t) = 35 + 5 exp(−k(t−10)). Heat-transfer coefficient is held constant. Curves are sampled every 0.5 minute; the table shows five-minute intervals. Real cooling can require a more detailed model.
Both fit. Their predictions disagree.
At 20 minutes, the straight line reaches 0°C and the cooling curve reaches about 27°C. Fitting the supplied readings alone does not tell us which assumption is appropriate.
The physical assumption rules out the straight line.
For passive cooling under this simple model, an object approaches a steady 20°C room temperature. It does not keep cooling below it. The curve now has a reason beyond fitting two points.
The same law needs the new room temperature.
If the room changes to 35°C after ten minutes, the calculated temperature at 20 minutes is about 37°C. Keeping the old room assumption gives about 27°C. Physics cannot correct an input the model was never given.
Given readings: 0 min: 80°C; 10 min: 40°C.
Straight-line fit Time · minutes Temperature · °C 0 80.0 5 60.0 10 40.0 15 20.0 20 0.0 Cooling in a steady 20°C room Time · minutes Temperature · °C 0 80.0 5 54.6 10 40.0 15 31.5 20 26.7 Room changes to 35°C at 10 min Time · minutes Temperature · °C 0 80.0 5 54.6 10 40.0 15 37.9 20 36.7 Adding physics to training does not guarantee success.
Aditi Krishnapriyan and colleagues showed another limit in a 2021 study. Penalties for violating physical equations could make some training problems difficult to optimise: a network capable of expressing a solution might still fail to learn it. The researchers also explored ways to improve training. Their result concerns specific methods and problems, not every physics-informed model.
That leaves two distinct checks. Does the model solve the problem it was given? And was that the right problem for the physical situation? Better optimisation can address the first while leaving the second untouched.
The scarce skill may be deciding what deserves a test.
In each case, people decided what was worth asking, what counted as progress and what could be checked. A search can work extremely well within those choices and still miss an important question outside them.
Atlas’s interpretation is that, as proposals become cheaper to generate, evaluating them may become the bottleneck. Some mathematical checks can be automated. In physical research, suitable instruments, materials and experiments may remain expensive or slow. Access to a model does not by itself provide access to a laboratory.
For anyone using AI in research or analysis, a useful habit is to pair each proposal with a check that could distinguish it from a plausible rival. What observation would tell them apart? An answer that tells you what to test next can be more valuable than one that merely sounds complete.
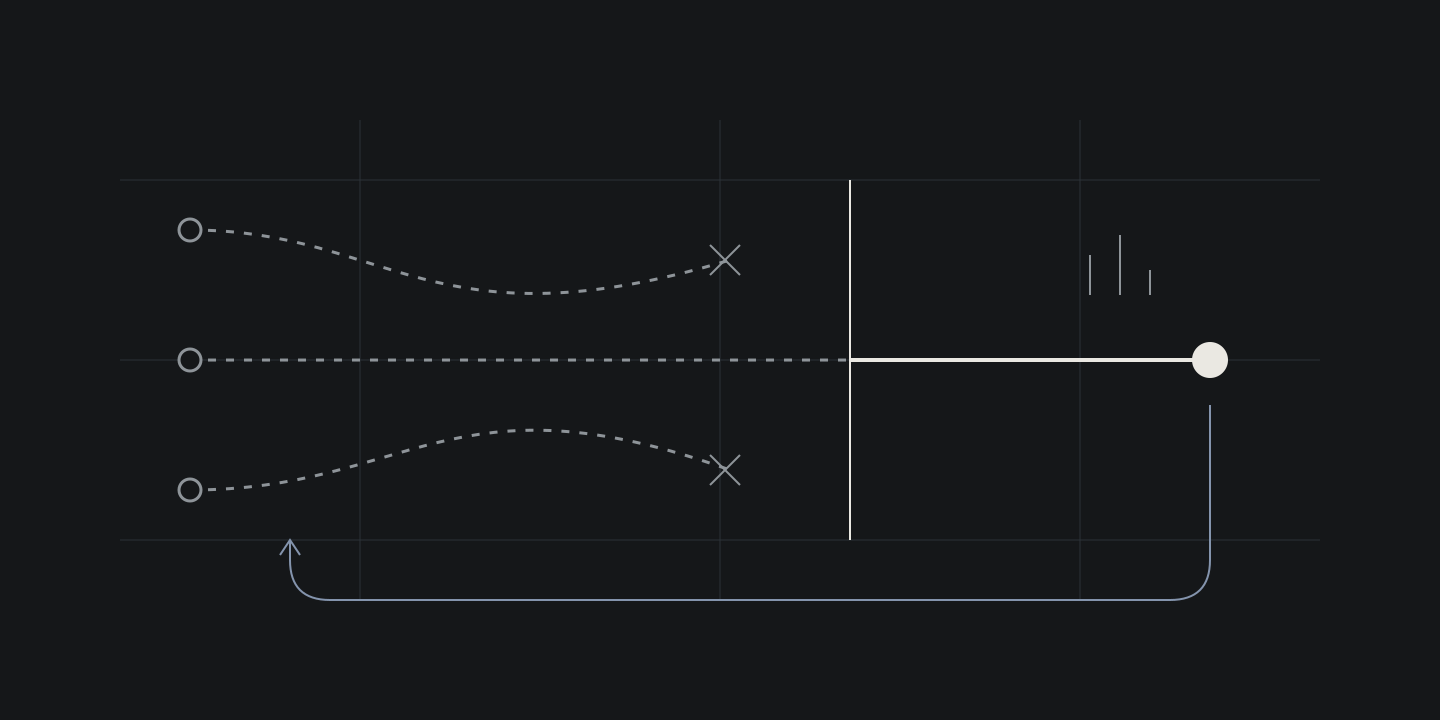
Illustration Proposals become useful knowledge when they survive checks. What the test reveals can guide the next search.
Sources in this version
- Mathematical discoveries from program search with large language models ↗Published article; linked access version identified below · FunSearch: Evaluation; Cap sets; Discussion; Figure 4Published 14 December 2023 · recorded in Atlas 23 October 2026
- Automated synthesis of oxygen-producing catalysts from Martian meteorites by a robotic AI chemist ↗Published article; linked access version identified below · Published abstract and Figures 1–4; author preprint pp. 6–9 and 16, models and experimental workflowPublished 13 November 2023 · recorded in Atlas 23 October 2026
- Accelerating scientific discovery with Co-Scientist ↗Published article; linked access version identified below · Recapitulating a breakthrough in AMR; Discussion; Methods: OverviewPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations ↗Published article; linked access version identified below · Author method page: Continuous Time Models, MSE = MSE_u + MSE_f; Data-driven DiscoveryPublished 1 February 2019 · recorded in Atlas 23 October 2026
- Characterizing possible failure modes in physics-informed neural networks ↗Published article; linked access version identified below · Sections 2–4: failure modes, loss landscapes, curriculum and sequence learningPublished 2021 · recorded in Atlas 23 October 2026
- Researchers
Revision 1 · First recorded version · reviewed
Explains AI-assisted discovery through mathematical, chemical and biomedical research, with interactive mechanisms.
Answer in this version
Trace one discovery claim from proposal to check. Identify who designed the test, what could fail, and whether anyone has reproduced the finding.
What remained unresolved
Prospective comparisons with realistic baselines, failed attempts, total experimental costs and independent replication.
Takeaway and scope
Yes—AI can help discover new knowledge. The strongest cases connect generated ideas to checks outside the model: executable rules, experiments and measurements. Novelty and correctness both need evidence.
Concrete research cases, with different kinds of evidence. No claim that AI can autonomously solve science as a whole.
A generated construction exceeded the known record
FunSearch reported a new 512-point cap set in eight dimensions.
A 2023 result for a defined mathematical problem, not proof of general scientific autonomy.
Predicted candidates were made and measured
The robotic chemistry study combined theoretical calculations, neural networks and physical experiments to identify a catalyst.
A laboratory demonstration on Earth within a defined chemistry setup; neither a Mars deployment nor an independently replicated general discovery system.
Rediscovery and a new discovery are different claims
Co-Scientist recovered an unpublished bacterial gene-transfer finding in a reported two days.
This timing describes hypothesis generation, not the completion of the underlying laboratory work.
Physical laws can shape the training objective
The classical PINN setup combines fitting observations with penalising disagreement with specified differential equations.
A soft penalty is not exact enforcement; known equations and boundary conditions still need to match the problem.
Physics-informed training can still fail
The study traced failures to difficult optimisation, despite sufficient network capacity.
These are specific 2021 methods and benchmark problems, not evidence that all subsequent physics-informed models fail.
Explanation in this version
A new result can start with old knowledge.
A model’s training material is a starting point. It can learn patterns for composing code or proposing structures, then use them to generate candidates that no one supplied as finished answers. Most candidates may be useless. A search process can still improve if it has a reliable way to recognise a better one.
To understand how that happens, look at the whole system: who defines the problem, what the model can propose, what tests the proposal, and how the result changes the next attempt. A fluent answer alone tells us little about those steps.
Novelty also depends on who already knew. A result can be new to the model, new to one research team, or new to the scientific record. Those are different achievements, as the following cases show.
A mathematical answer that could be checked.
In 2023, Bernardino Romera-Paredes and colleagues at Google DeepMind and universities reported FunSearch. A language model proposed small programs; an evaluator ran them, discarded invalid outputs and scored useful ones. Better programs informed later prompts.
For the cap-set problem—finding large sets of points that avoid a specified three-point pattern—it produced a construction with 512 points in eight dimensions, exceeding the then-known record. It did not solve the whole problem or prove that 512 was the largest possible.
The human contribution included the problem, evaluator and program structure. The model supplied variations. Search and checking turned some of those variations into a new mathematical result.
In chemistry, the answer has to survive a measurement.
A team led by the University of Science and Technology of China (USTC), including Jun Jiang, Weiwei Shang and Yi Luo, reported a robotic chemist in 2023. It used meteorite material to develop catalysts for releasing oxygen from water. This was a laboratory demonstration on Earth.
The system combined theoretical calculations with experimental data to select promising candidates, then made and tested the proposed catalyst. The result was a material whose performance had been measured in a setup designed by researchers. The models and robot did different jobs.
A calculation can make a candidate worth trying. The measurement supplies information the prediction itself cannot provide: how that material behaves under those test conditions.
Two days of hypotheses are not years of experiments.
Google’s Co-Scientist offers a different example. Its 2026 Nature paper reports that the system recovered, in two days, a mechanism of bacterial gene transfer already found by an experimental team but not yet published. Matching a withheld result is valuable evidence of hypothesis-generation ability. Establishing that result had still required laboratory work.
The same paper describes other suggestions followed by laboratory validation. It also acknowledges preliminary evidence, limits to factual accuracy and gaps in access to scientific literature. This is a collaboration between Google and academic researchers, not an independent assessment of Google’s system.
The distinction is useful whenever a headline compresses a long research programme into the time taken to generate an idea. Ask what the clock includes.
The proposal and the judge do different jobs.
Notice what sits outside the model in each case. A coded rule can reject an invalid construction. An instrument can reveal a failed prediction. A withheld result can test whether the system recovers something it was not explicitly told. None of those checks becomes stronger merely because several language models agree.
The feedback is therefore a central design choice: what would make the system change its mind? If the only response is that another model finds the answer convincing, the process may refine plausibility without acquiring new evidence.
Research pathways · Atlas synthesis The test changes what a result can establish.
FunSearch · provider and academic research · 2023
- Researchers
Frame
Define the problem and checker.
- Language model
Propose
Generate a candidate program.
- Evaluator
Check
Run it; reject invalid outputs.
- Search system
Keep
Retain useful constructions.
Checked programs help shape the next proposals.
What this establishedA construction beyond the then-known record.
A better construction need not be the best possible one.
These are different studies, not a head-to-head performance comparison. The paths simplify the reported methods.
Read all research pathways
Mathematics
FunSearch · provider and academic research · 2023
- Frame · Researchers. Define the problem and checker.
- Propose · Language model. Generate a candidate program.
- Check · Evaluator. Run it; reject invalid outputs.
- Keep · Search system. Retain useful constructions.
Checked programs help shape the next proposals.
What this establishedA construction beyond the then-known record.
A better construction need not be the best possible one.
Study & evidence ↗Chemistry
USTC-led academic research · China · 2023
- Define · Researchers. Choose materials and test conditions.
- Predict · Models. Select promising compositions.
- Make · Laboratory robot. Prepare the material.
- Measure · Instruments. Test catalytic performance.
Experimental data inform the predictive model.
What this establishedA candidate supported by laboratory measurements.
Performance outside the tested conditions remains a separate question.
Study & evidence ↗Rediscovery
Co-Scientist · provider and academic research · 2026
- Withhold · Researchers. Keep the result unpublished.
- Propose · AI system. Generate explanations.
- Compare · Researchers. Check against the experimental finding.
- Interpret · Readers. Separate rediscovery from first discovery.
What this establishedA hypothesis matching an unpublished finding.
This does not replace the experiments that established it.
Study & evidence ↗Physics narrows the possibilities. Assumptions still matter.
Physics-informed neural networks, or PINNs, offer another way to guide a model. In the classical approach described by Maziar Raissi, Paris Perdikaris and George Karniadakis, training penalises both disagreement with observations and violations of specified physical equations. The model is asked to fit the data and respect a chosen description of the world.
This can help where observations are sparse, or help estimate unknown parameters within an assumed equation. But solving a known equation, inferring a parameter and discovering a new physical law are different claims. The illustration below shows how assumptions shape a prediction; it does not train a neural network.
Atlas illustration · calculated, not measured Two readings do not determine the future.
Imagine an object at 80°C, then 40°C ten minutes later. Both curves below pass through those readings. Look at what happens after them.
- Straight-line fit
- Cooling in a steady 20°C room
- Given readings
Both fit. Their predictions disagree.
At 20 minutes, the straight line reaches 0°C and the cooling curve reaches about 27°C. Fitting the supplied readings alone does not tell us which assumption is appropriate.
A calculated teaching example, not measured data, a trained PINN or evidence of model accuracy.
Read all cases, values & method
Newton’s cooling model: T(t) = 20 + 60 exp(−kt), with k = ln(3)/10 per minute. The line is T(t) = 80 − 4t. In the changed-room case, from t = 10: T(t) = 35 + 5 exp(−k(t−10)). Heat-transfer coefficient is held constant. Curves are sampled every 0.5 minute; the table shows five-minute intervals. Real cooling can require a more detailed model.
Both fit. Their predictions disagree.
At 20 minutes, the straight line reaches 0°C and the cooling curve reaches about 27°C. Fitting the supplied readings alone does not tell us which assumption is appropriate.
The physical assumption rules out the straight line.
For passive cooling under this simple model, an object approaches a steady 20°C room temperature. It does not keep cooling below it. The curve now has a reason beyond fitting two points.
The same law needs the new room temperature.
If the room changes to 35°C after ten minutes, the calculated temperature at 20 minutes is about 37°C. Keeping the old room assumption gives about 27°C. Physics cannot correct an input the model was never given.
Given readings: 0 min: 80°C; 10 min: 40°C.
Straight-line fit Time · minutes Temperature · °C 0 80.0 5 60.0 10 40.0 15 20.0 20 0.0 Cooling in a steady 20°C room Time · minutes Temperature · °C 0 80.0 5 54.6 10 40.0 15 31.5 20 26.7 Room changes to 35°C at 10 min Time · minutes Temperature · °C 0 80.0 5 54.6 10 40.0 15 37.9 20 36.7 Physics in the training objective is no guarantee.
Aditi Krishnapriyan and colleagues demonstrated another limit in a 2021 study: penalties for violating physical equations could make some training problems difficult to optimise. A network capable of expressing a solution might still fail to learn it. They also explored ways to improve training. The result concerns specific methods and problems, not every physics-informed model.
That leaves two distinct checks. Does the model solve the problem it was given? And was that the right problem for the physical situation? Better optimisation can address the first while leaving the second untouched.
The scarce skill may be deciding what deserves a test.
Across these cases, people still determined what was worth asking, what counted as progress and what could be checked. A search can be highly effective within those choices while overlooking an important question outside them.
Atlas’s interpretation is that cheaper proposals can shift the bottleneck towards evaluation. In some mathematical problems, checks can be automated. In physical research, suitable instruments, materials and experiments may remain expensive or slow. Access to a model does not by itself provide access to a laboratory.
For anyone using AI in research or analysis, a useful habit is to pair each proposal with a check that could distinguish it from a plausible rival. What observation would tell them apart? An answer that tells you what to test next can be more valuable than one that merely sounds complete.
Illustration Proposals become useful knowledge when they survive checks. What the test reveals can guide the next search.
Sources in this version
- Mathematical discoveries from program search with large language models ↗Published article; linked access version identified below · FunSearch: Evaluation; Cap sets; Discussion; Figure 4Published 14 December 2023 · recorded in Atlas 23 October 2026
- Automated synthesis of oxygen-producing catalysts from Martian meteorites by a robotic AI chemist ↗Published article; linked access version identified below · Published abstract and Figures 1–4; author preprint pp. 6–9 and 16, models and experimental workflowPublished 13 November 2023 · recorded in Atlas 23 October 2026
- Accelerating scientific discovery with Co-Scientist ↗Published article; linked access version identified below · Recapitulating a breakthrough in AMR; Discussion; Methods: OverviewPublished 19 May 2026 · recorded in Atlas 23 October 2026
- Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations ↗Published article; linked access version identified below · Author method page: Continuous Time Models, MSE = MSE_u + MSE_f; Data-driven DiscoveryPublished 1 February 2019 · recorded in Atlas 23 October 2026
- Characterizing possible failure modes in physics-informed neural networks ↗Published article; linked access version identified below · Sections 2–4: failure modes, loss landscapes, curriculum and sequence learningPublished 2021 · recorded in Atlas 23 October 2026
- Researchers
Where the sources sit in time.
A retrospective selection: publications used in this question and its discovery, ordered by their publication dates. This is a small historical overview, not a complete account of the field or evidence of a research trend.
Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations ↗
Publication date; this is not a date of an Atlas replication.
Characterizing possible failure modes in physics-informed neural networks ↗
Publication date; this is not a date of an Atlas replication.
Automated synthesis of oxygen-producing catalysts from Martian meteorites by a robotic AI chemist ↗
Publication date; this is not a date of an Atlas replication.
Mathematical discoveries from program search with large language models ↗
Publication date; this is not a date of an Atlas replication.
Accelerating scientific discovery with Co-Scientist ↗
Publication date; this is not a date of an Atlas replication.